Google UGC Spam Prevention: Noindex, rel=ugc and Search Console
How platforms can keep share-only pages out of Search, qualify untrusted links, gate indexing by reputation, and detect abuse early
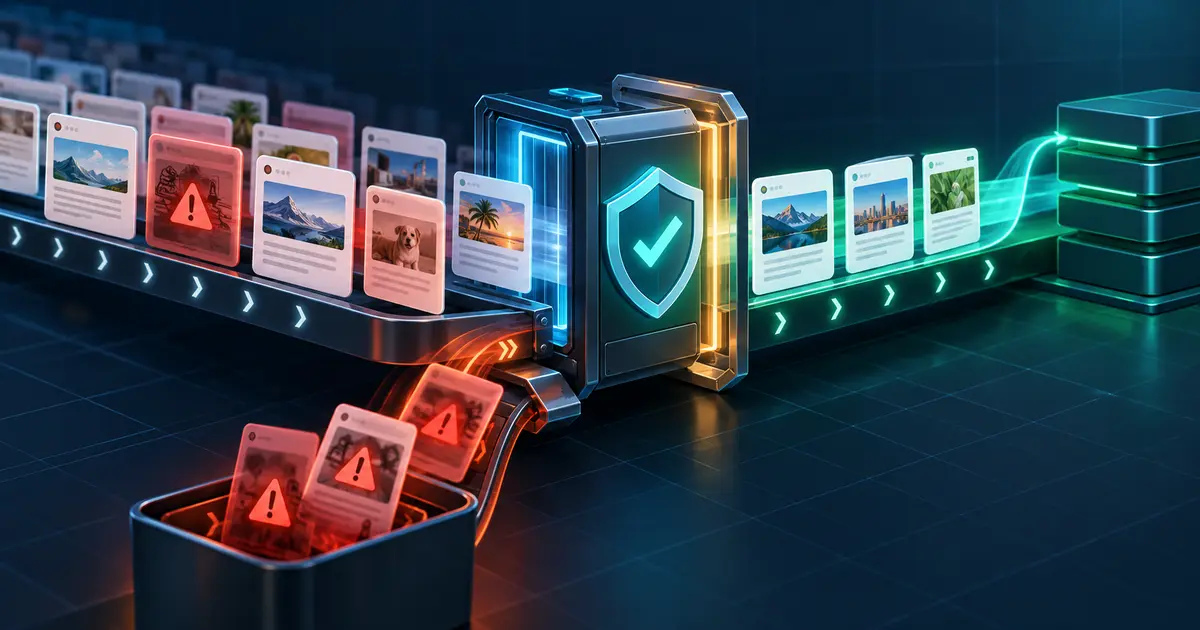
Google updated its guidance for preventing user-generated spam on October 26, 2026. The revision adds a clearer rule for platforms that create shareable pages, generated outputs, or interactive tools: decide whether each page is genuinely meant for public Search, rather than indexing every URL by default.
The update is relevant to forums, SaaS products, website builders, profile platforms, public file tools, AI generators, marketplaces, and any service where users can publish a URL. The practical challenge is not simply blocking spam after it appears. It is designing an indexing lifecycle that prevents low-trust or share-only pages from entering Search in the first place.
This guide separates Google's documented recommendations from Rubic8's implementation suggestions. It explains when to use noindex, why robots.txt is not a privacy control, how to qualify links in untrusted content, and how to monitor abuse before a manual action or index-quality problem becomes visible.
What changed on October 26, 2026?
Google's Search documentation update log says the user-generated spam guide was expanded in two areas:
- blocking indexing of content created for direct sharing rather than Search discovery; and
- monitoring abuse through Search Console and platform-level anomaly signals.
The underlying anti-spam principles are not new. Google has long recommended moderation, account controls, link qualification, and reputation systems. The important change is the explicit treatment of modern shareable outputs: generated pages, web apps, collaboration artifacts, and utility URLs that may be public on the web but were never intended to become landing pages in Search.
Fact: Google says platforms should consider applying a noindex rule or blocking crawling by default when a page exists for direct sharing, collaboration, or utility rather than public search discovery.
Rubic8 interpretation: Indexability should be a product state, not an accidental side effect of generating a public URL. A page should become indexable only after it has a clear public purpose, enough useful content, and an accountable owner.
Classify pages before choosing a crawler control
Start with the page's intended audience and sensitivity. The same technical control is not correct for every page.
| Page type | Recommended starting state | Reason |
|---|---|---|
| Public, reviewed UGC with standalone value | Indexable after approval | It is intentionally published for discovery and meets the platform's quality rules. |
| New-user post awaiting reputation | noindex |
Google can crawl the page but should not place it in Search until trust requirements are met. |
| Share-only result, temporary output, or collaboration page | noindex by default |
The URL is usable by people with the link but has no public-search purpose. |
| Private or confidential content | Authentication or removal | Robots directives are not access control and do not make a URL private. |
| Abusive or policy-violating page | Remove or return an appropriate error | Keeping known spam available with only noindex leaves users and the platform exposed. |
A single site may need all five states. Avoid one global switch that treats a high-quality public forum answer, a private draft, and an automatically generated preview as equivalent URLs.
Use noindex correctly—and avoid the robots.txt trap
For an HTML page that can remain publicly accessible but should not appear in Search, place a robots meta tag in the returned document:
<meta name="robots" content="noindex, follow">For non-HTML responses or when the application controls headers more reliably than templates, send an HTTP response header:
X-Robots-Tag: noindexGoogle's separate noindex documentation contains a critical implementation detail: Googlebot must be allowed to crawl the URL to see the directive. If robots.txt blocks the page, Google may never read the meta tag or header. A blocked URL can still be known from links and may remain represented in Search without a normal snippet.
This means “Disallow plus noindex” is not a reliable deindexing recipe. Choose the control according to the goal:
- Prevent indexing while keeping the page publicly reachable: allow crawling and return
noindex. - Reduce crawling of a low-value URL space: use robots.txt only after reviewing whether existing indexed URLs first need to expose
noindex. - Protect confidential information: require authentication or remove the content.
Rubic8's Robots.txt Generator & Tester can help inspect allow and disallow logic. It cannot confirm that a page contains a robots meta tag, remove an indexed URL, or turn robots.txt into authentication.
Gate indexing with reputation instead of account age alone
Google suggests placing noindex on posts from new users without reputation, then allowing indexing after the user gains trust. The recommendation reduces the search incentive for accounts created only to publish links or large volumes of low-value pages.
A production reputation gate should use more than elapsed time. A two-year-old dormant account can be compromised, while a new verified contributor may publish excellent material. Useful signals include:
- verified email, organization, or payment relationship where appropriate;
- approved contributions and reports from trusted users;
- edit and deletion history;
- rate, similarity, and destination patterns in submitted links;
- moderator decisions and successful appeals; and
- recent security events or unexpected account behavior.
Rubic8 recommendation: store index eligibility as an explicit field with an audit trail. Do not infer it only at render time from a score that can change without explanation.
{
  "search_visibility": "noindex",
  "reason": "new_contributor_review",
  "reviewed_by": null,
  "changed_at": "2026-10-28T00:00:00Z"
}
When a moderator approves the page, change the state, remove the noindex directive, add the URL to the appropriate sitemap if it belongs there, and make it discoverable through relevant internal links. Approval should not automatically submit every historical URL or bypass normal crawl and indexing systems.
Qualify links in untrusted user content
Google recommends adding rel="nofollow" or rel="ugc" to links in untrusted content because many spammers are motivated by ranking credit.
<a href="https://example.net/offer" rel="ugc nofollow">
  User-submitted link
</a>
ugc communicates that the link came from user-generated content. nofollow is a broader qualification. Platforms can apply one or both based on their policy. The attribute does not make the destination safe, prevent phishing, or replace moderation; it only describes how search systems should treat the link relationship.
Sanitize attributes and protocols server-side. Reject executable schemes, normalize redirects, and render a warning or intermediate page for destinations that require extra caution. Do not let users override link attributes with raw HTML.
Detect abusive accounts before they create an index problem
Google's guide lists form completion time, request volume from an IP range, user agents, usernames, and other submitted values as useful signals. These are indicators, not proof. Shared networks, accessibility tools, privacy services, and automation used for legitimate workflows can all create false positives.
A safer model combines signals and applies graduated responses:
- Observe: log creation rate, destination domains, similarity, account age, and moderation outcomes.
- Limit: slow high-volume creation and cap the number of public URLs a new account can produce.
- Challenge: request verification when risk increases.
- Review: queue suspicious pages for human approval and keep them
noindex. - Block: remove confirmed abuse and related accounts or infrastructure when evidence supports it.
- Appeal: give legitimate users a way to correct a false positive.
Manual approval remains valuable for consequential actions, but it should focus on uncertain or high-risk cases rather than making moderators inspect every benign edit.
Monitor Search Console for abuse signals
The October update explicitly recommends verifying the site or relevant subdomain in Search Console and reviewing several reports:
- Manual Actions: check whether Google has identified policy violations.
- Security Issues: look for hacked, deceptive, or harmful pages.
- Page Indexing: watch unexpected growth in indexed pages or changes in exclusion reasons.
- Search performance: investigate sudden impressions or queries unrelated to the platform's purpose.
Search Console data should be combined with application metrics. Google also recommends alerting on spikes in newly published public pages or cases where a small number of users produce a large share of indexable URLs.
| Signal | Possible explanation | First check |
|---|---|---|
| Sharp rise in indexed pages | New feature, crawl discovery, or automated spam | Compare release logs, sitemap growth, creators, and Page Indexing samples. |
| Unrelated queries or countries | Legitimate expansion or compromised/abusive UGC | Inspect landing pages, account history, language, redirects, and outbound links. |
| Many public pages from a few users | Power users, imports, or scaled abuse | Review similarity, destination domains, approval history, and rate limits. |
| Unexpected encoded JavaScript | App code, obfuscation, injection, or malware | Compare with trusted builds and investigate the creating account. |
Do not delete content or ban users based on one graph. Preserve examples, review server logs, and distinguish a product launch from abuse before applying irreversible actions.
Build a repeatable UGC indexing lifecycle
A practical state machine makes policy enforceable:
- Draft: authenticated or unlisted; not eligible for indexing.
- Shared: accessible by link but returns
noindex. - Pending review: public URL,
noindex, qualified outbound links. - Published: reviewed, indexable, internally linked, and eligible for the correct sitemap.
- Restricted: temporarily
noindexwhile an issue is reviewed. - Removed: content deleted or an appropriate HTTP error returned.
Keep template behavior, HTTP headers, sitemap inclusion, canonical URLs, internal links, and API responses aligned with the same state. A common failure is marking a page noindex while continuing to promote it in an XML sitemap as a canonical public landing page.
A 30-minute audit for an existing platform
- List every feature that can create a public URL: posts, profiles, uploads, generated reports, previews, shared outputs, and app pages.
- Classify each feature as public-search, share-only, private, pending, or removed.
- Fetch one example from each state without administrator cookies.
- Inspect HTTP status, robots meta,
X-Robots-Tag, canonical, outbound link attributes, and sitemap inclusion. - Check whether robots.txt prevents Google from seeing a required
noindex. - Review Page Indexing and Search performance for unexpected URL or query growth.
- Identify the accounts responsible for the largest number of indexable pages.
- Record the baseline and assign an owner for each remediation.
For public pages, Rubic8's SEO & AI Visibility Checker can inspect several static HTML, robots.txt, and sitemap signals. It does not log into private pages, see Search Console data, judge whether a user is trustworthy, or prove that Google indexed a URL.
For a wider recovery checklist after a ranking or spam event, see Rubic8's Google September 2026 Spam Update guide. The older article covers site-wide diagnosis; this guide focuses specifically on preventing abuse in user-published URL systems.
Common mistakes to avoid
- Indexing every generated or shared URL because it returns HTTP 200.
- Using robots.txt as a privacy or authentication mechanism.
- Blocking a URL in robots.txt and assuming Google can still read its
noindex. - Leaving untrusted outbound links unqualified.
- Making account age the only reputation signal.
- Automatically publishing AI-generated pages without ownership or review.
- Treating a Search Console spike as proof of abuse without checking releases and logs.
- Keeping removed or restricted URLs in the public sitemap indefinitely.
Final recommendation
Google's October 26 update turns an SEO cleanup problem into a product-design decision: not every public URL deserves to become a Search landing page. Platforms should define search visibility before launch, keep share-only and low-trust pages noindex, qualify links in untrusted content, and promote pages to indexable status only through an auditable review process.
Start by mapping URL-producing features and checking one live example from every state. Then connect Search Console anomalies to creator and publishing metrics. The goal is not to block all UGC; it is to preserve valuable first-hand contributions while removing the search incentive for scaled abuse.
Official sources
- Google Search documentation updates — October 26, 2026 entry
- Prevent user-generated spam on your site and platform
- Block Search indexing with noindex
- Control what you share with Google Search
- Spam policies for Google web search
Last reviewed: October 28, 2026. Google may revise Search controls and reporting interfaces; verify the official documentation before changing production behavior.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
