GPT-6.1 Terra API Guide: Pricing, Context and Computer Use
How to evaluate OpenAI's fast visual and computer-use model, estimate real costs, and deploy it with safer approval boundaries
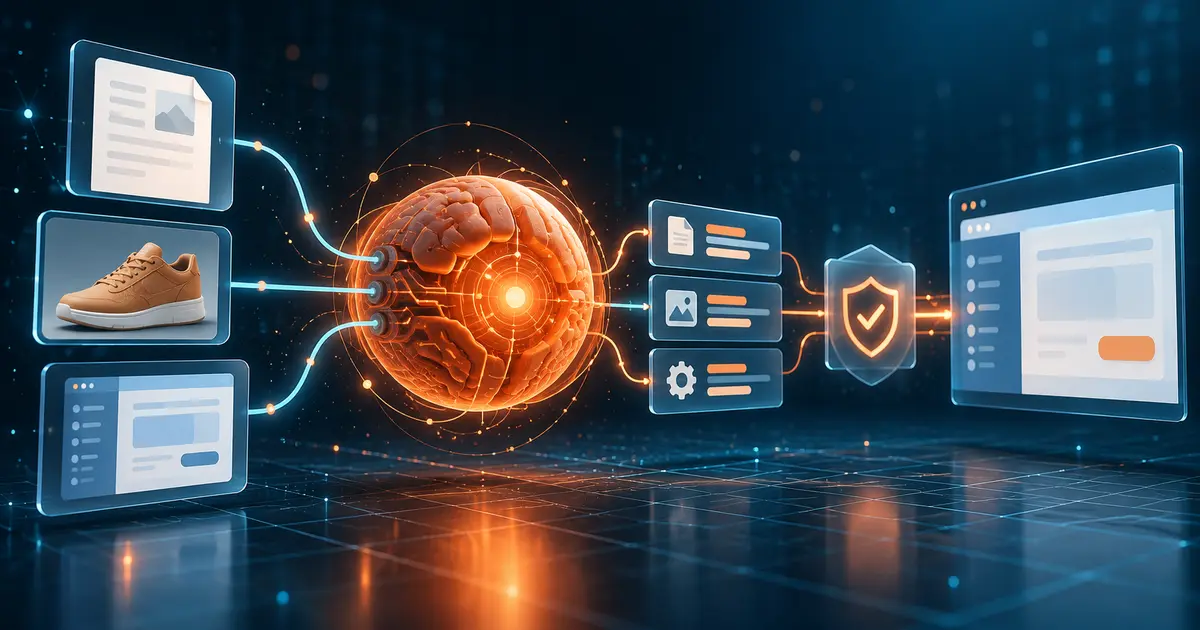
GPT-6.1 Terra arrived on October 26, 2026 as OpenAI's fast, lower-cost model for visual reasoning, computer use, and high-volume knowledge work. It is available in the API as gpt-6.1-terra, with a 1,050,000-token context window, up to 128,000 output tokens, image input, structured outputs, function calling, and the computer-use tool.
The headline price is $1 per million input tokens, $0.05 per million cached input tokens, and $5 per million output tokens at the Standard tier. Those numbers make Terra substantially cheaper than GPT-6.1 Sol, but the cheapest model on a price list is not automatically the cheapest system in production. Long-context multipliers, tool fees, retry rates, reasoning effort, and human-review costs still matter.
This guide separates OpenAI's published facts from Rubic8's implementation recommendations. It shows where Terra fits, how to estimate cost, how to call it safely, and when a more capable or cheaper model may be the better choice.
GPT-6.1 Terra at a glance
| Specification | Current value | Practical implication |
|---|---|---|
| API model ID | gpt-6.1-terra |
Pin this exact identifier in tests and configuration. |
| Context window | 1,050,000 tokens | Large documents and repositories can fit, but requests above 272K input tokens cost more. |
| Maximum output | 128,000 tokens | Suitable for long reports or code changes; set a lower application limit when possible. |
| Knowledge cutoff | June 1, 2026 | Use web search or retrieval for newer facts. |
| Input modalities | Text and images | Useful for screenshots, technical drawings, product images, and documents. |
| Output modality | Text | Image, audio, and video generation are separate tools or models. |
| Reasoning effort | none, low, medium, high, xhigh, max |
medium is the documented default; test effort per workflow. |
| Fine-tuning | Not supported | Use prompts, tools, retrieval, skills, and evaluations instead. |
Fact: OpenAI describes Terra as a fast, efficient model for detailed visual reasoning, precise computer use, and natural writing. The model page lists streaming, function calling, structured outputs, web search, file search, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search as supported through the Responses API.
Rubic8 interpretation: Terra's clearest position is between a very inexpensive classifier/extractor and a frontier model. It is a strong candidate when a task requires screen understanding or multi-step action but must run often enough that Sol or Astra would be costly.
Pricing: the simple numbers and the expensive edge cases
OpenAI's current Standard prices per one million tokens are:
- Input: $1.00
- Cached input read: $0.05
- 30-minute cache write: $1.25
- 12-hour cache write: $2.50
- Output: $5.00
Batch and Flex processing are listed at 50% below Standard. Fast mode costs twice the Standard rate, and regional processing adds a 10% premium where available. Tool-specific fees can apply in addition to model-token charges.
The most important pricing caveat is long context. When input exceeds 272,000 tokens, OpenAI says the entire request is billed at twice the input and cache rates and 1.5 times the output rate. Crossing the threshold by a small amount can therefore change the price of every token in that request.
A practical cost example
Suppose a document workflow sends 80,000 uncached input tokens and receives 8,000 output tokens:
Input:  80,000 / 1,000,000 × $1.00 = $0.08
Output:  8,000 / 1,000,000 × $5.00 = $0.04
Total model cost:                         $0.12
If 60,000 of those input tokens are reusable and served from cache, the model-token estimate becomes approximately $0.063, excluding the initial cache write and any tools. This is an arithmetic illustration, not a benchmark or a guarantee of your bill.
For budgeting, record four fields per request: uncached input tokens, cached reads, output tokens, and tool calls. Also log reasoning effort and whether the request crossed the 272K threshold. Average cost alone can hide a small number of very expensive long-context calls.
How Terra differs from GPT-6.1 Sol and GPT-6 Astra
OpenAI positions GPT-6 Astra as its most capable model and GPT-6.1 Sol as the stronger choice for the most complex coding work. Terra prioritizes speed and lower unit cost while retaining computer use and visual reasoning.
| Choose | When the workflow primarily needs | Watch for |
|---|---|---|
| GPT-6.1 Terra | High-volume visual work, desktop actions, document processing, routine coding, and natural writing | Complex reasoning may still justify Sol or Astra; large inputs trigger price multipliers. |
| GPT-6.1 Sol | Harder agentic coding and complex professional workflows | Higher price can dominate at scale. |
| GPT-6 Astra | Maximum capability for the hardest, highest-value work | Use an evaluation to prove that the quality gain is worth the cost. |
This is a workload-routing decision, not a universal ranking. A useful policy is to start with Terra, escalate only on known hard cases, and measure the result against a fixed evaluation set. Do not route solely from prompt length; difficulty, visual ambiguity, required autonomy, and the cost of a wrong action matter more.
What OpenAI's benchmarks do and do not prove
OpenAI reports substantial improvements over GPT-5.6 Terra on its published evaluations. Examples include a 50.3% score at maximum reasoning on Terminal-Bench 4.0 versus the predecessor's published 21.5%, and a reduction in error rate on OpenAI's internal error-inducing prompt set from 53.6% to 16.7% at low reasoning effort.
These are vendor-reported results under specified evaluation conditions. They are useful evidence of progress, but they are not a benchmark of your application, prompt, tools, latency target, or data. Rubic8 has not independently reproduced these scores and does not convert them into a claim about production accuracy.
Build a small evaluation set from your real failure modes: blurred screenshots, conflicting invoice totals, ambiguous form controls, long PDFs, stale facts, and tool errors. Score task completion, factual correctness, action safety, latency, and total cost. A model upgrade is successful only if the workflow improves on the metrics that matter to you.
Make your first Responses API call
For new integrations, use the Responses API. OpenAI states that tool calling for Terra requires it. The following example asks for a short implementation plan without invoking tools:
curl https://api.openai.com/v1/responses \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "gpt-6.1-terra",
    "reasoning": {"effort": "medium"},
    "input": "Design a safe workflow for extracting invoice totals and entering them into an accounting system. Separate automatic steps from approval steps."
  }'
Keep the API key on the server. Do not expose it in browser JavaScript, mobile binaries, screenshots, logs, or online JSON tools. For sanitized test fixtures, Rubic8's JSON Formatter can make nested Responses API output easier to inspect, while the JSON Validator can catch malformed JSON. Syntax validation does not establish that an answer is true or safe.
Use structured outputs for downstream systems
When software will consume the result, define a schema instead of parsing prose. For an invoice workflow, a safe result might contain the document ID, currency, subtotal, tax, total, confidence notes, and an explicit review flag.
{
  "invoice_id": "INV-2048",
  "currency": "USD",
  "total": 1842.50,
  "needs_review": true,
  "review_reason": "Subtotal is partially obscured"
}
Validate the schema in your application, then validate business rules separately. A syntactically correct number can still be wrong. Compare currency, supplier, purchase-order limits, duplicate invoice IDs, and arithmetic before writing anything to a financial system.
Design computer-use workflows around approval boundaries
Computer use is one of Terra's headline capabilities, but screen control changes the risk profile. Reading a dashboard is different from submitting a payment, deleting a record, or granting access.
A practical production pattern is:
- Observe: capture the current screen and relevant application state.
- Plan: ask the model to state the next action and its expected result.
- Validate: enforce allowed domains, applications, actions, and data boundaries outside the model.
- Act: execute one bounded action.
- Verify: inspect the new state instead of assuming the action succeeded.
- Escalate: require human confirmation for financial, permission, deletion, publication, and other consequential actions.
Do not give a model unrestricted access merely because it passed a demonstration. Prompt injection can arrive through web pages, PDFs, emails, images, tool descriptions, or retrieved content. Treat those inputs as untrusted data and keep authorization in deterministic application code.
Manage a one-million-token context window carefully
A 1.05M context window makes it technically possible to send very large repositories or document collections, but capacity is not a content strategy. Irrelevant context can raise cost, increase latency, and make the model's job harder.
Use retrieval or staged summarization to send only the evidence needed for the current decision. Preserve stable instructions at the beginning so prompt caching can reuse them. Keep volatile user data and fresh retrieval results later in the prompt. Measure cache-hit rates instead of assuming that repeated content is cached.
Before sending a large request, estimate token size and warn when it approaches 272K. If the task can be divided without losing cross-document reasoning, split it. If it cannot, budget for the documented multiplier and run a quality comparison against the smaller-context approach.
Choose reasoning effort with an evaluation, not intuition
Terra supports six effort settings from none to max, with medium documented as the default. Higher effort may improve difficult tasks, but it can use more reasoning tokens and increase latency.
Start with medium for mixed workloads. Test none or low for rewriting, classification, and simple extraction. Test high or above only when your evaluation shows a material quality gain on hard visual, coding, or planning cases. Store the chosen effort alongside the prompt version so regressions are traceable.
Migration checklist for GPT-5.6 Terra users
- Change the model ID in a staging environment, not directly in production.
- Re-run task-specific evaluations; do not rely only on OpenAI's benchmarks.
- Review prompts for obsolete model-specific workarounds.
- Test every tool and schema through the Responses API.
- Check image inputs, especially low-resolution screenshots and technical drawings.
- Compare reasoning-effort settings on quality, latency, and cost.
- Measure cached reads and cache writes separately.
- Add monitoring for requests above 272K input tokens.
- Preserve human approval for consequential computer actions.
- Keep a rollback path to the previous model while production results stabilize.
Where GPT-6.1 Terra is most useful
Good initial candidates include matching product photos to catalog records, interpreting technical drawings, reading screenshots, preparing draft form entries, reviewing visual assets, extracting fields from documents with validation, and handling routine code or writing tasks at volume.
It is a weaker default when the task requires audio or video input, fine-tuning, the deepest possible coding reasoning, or unsupervised high-consequence action. In those cases, choose a supported model or redesign the workflow instead of stretching Terra beyond its documented capabilities.
Final recommendation
GPT-6.1 Terra is not simply a smaller GPT-6.1 Sol. Its combination of image understanding, computer use, large context, structured outputs, and lower pricing creates a distinct role for high-volume agent workflows.
Start with a bounded task, the Responses API, medium reasoning, strict schemas, and deterministic approval gates. Record real token and tool costs, watch the 272K long-context threshold, and compare Terra with Sol or Astra on the hard cases. That approach turns a model announcement into an evidence-based deployment decision.
Official sources
- OpenAI: Introducing GPT-6.1 Terra — October 26, 2026
- OpenAI API model page: GPT-6.1 Terra — specifications and pricing checked October 27, 2026
- OpenAI: Introducing GPT-6 Sol and Luna — model-family context
Last reviewed: October 27, 2026. Model availability, prices, rate limits, and tool support can change; verify the official model page before production rollout.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
