Cloudflare Clairic: Typed Data Extraction Without LLM-Generated JSON
Build confidence-aware extraction pipelines with typed fields, image inputs, and Workers AI
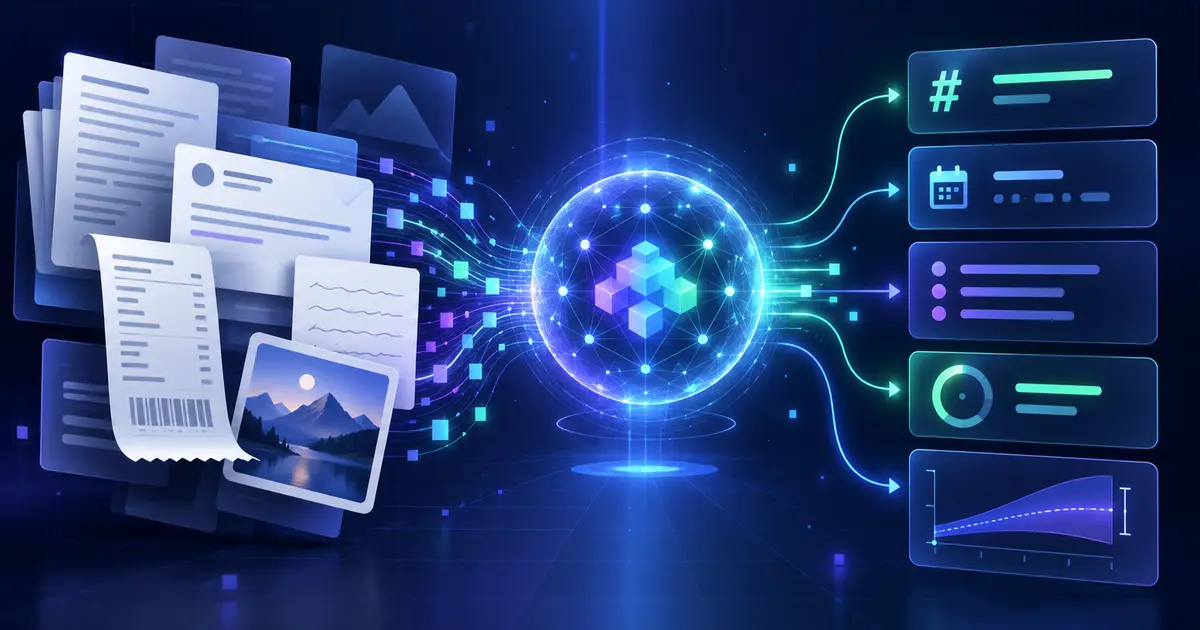
Many production AI pipelines use a large language model for a job that is narrower than language generation: read an invoice, support ticket, or report and return a few fields. The usual prompt asks for JSON, then the application parses it, validates it, retries malformed responses, and sends uncertain cases to review.
On October 19, 2026, Cloudflare introduced Clairic, a preview extraction model on Workers AI. Instead of generating a JSON document token by token, Clairic accepts unstructured text plus an explicit map of typed fields. It returns values, null probabilities, confidence signals, source spans for text, and uncertainty intervals for estimates and forecasts.
This guide explains what was actually announced, where Clairic differs from an LLM with structured output, and how to design a cautious extraction pipeline around it. Product claims are attributed to Cloudflare; operational recommendations are clearly identified as practical guidance rather than vendor guarantees.
What Cloudflare released
Clairic is available as the hosted Workers AI model @cf/cloudflare/clairic. Cloudflare describes it as a “System One-style” extraction model: a purpose-built model that performs a single forward pass and produces typed values rather than free-form text. The release is explicitly a preview, and Cloudflare says it plans to publish open weights later.
According to the official model page, Clairic has a 65,536-token context window, supports vision input, and costs $0.10 per million input tokens. The model generates no output tokens, so Cloudflare lists no output-token charge. Cloudflare also says requests typically complete in under a second; treat that as a vendor statement until you benchmark your own documents, region, Worker, and concurrency pattern.
A request contains two main parts:
state: the text to read or reason from, optionally accompanied by up to four embedded PNG, JPEG, or WebP images.fields: a map of names to typed field specifications, with optional plain-language instructions.
Cloudflare documents no field-count ceiling. If the field definitions cannot fit beside the input in one 8,192-token pass, the service splits them across parallel passes that each see the full input and merges the answers.
Clairic is not “another JSON mode”
An LLM with JSON mode or a structured-output schema still generates an answer. The schema can constrain its shape, but the model is producing tokens that represent numbers, dates, and strings. Clairic instead predicts values within declared types. That distinction changes the failure surface.
| Approach | Best at | Typical output | Main risk |
|---|---|---|---|
| Clairic extraction | Extracting or computing typed values | Values, spans, confidence, probability, intervals | A valid value can still be wrong |
| Decision model | Selecting from known options | Choice plus probabilities | The option set or policy can be incomplete |
| LLM structured output | Reasoning and flexible transformation | Generated object or text | Plausible but unsupported content |
| Rules and parsers | Stable, deterministic formats | Exact matches and computed fields | Brittleness when formats vary |
The important nuance is that “typed” does not mean “true.” Cloudflare’s own preview notes say every answer is well formed but not necessarily correct. Clairic can make a mistaken extraction, calculation, or prediction even when the response perfectly matches the requested type.
Supported field types
The launch changelog documents the following field types:
| Type | Returns | Example |
|---|---|---|
text |
An exact input span and character offsets | Invoice ID |
number |
A read or computed number honoring integer/decimal rules | Total including shipping |
date, time, datetime |
ISO-form calendar dates and valid times | Calculated due date |
duration |
A length of time in the requested unit | Days since delivery |
list |
Matching text, numbers, or dates in input order | Named contacts |
estimate |
A bounded distribution on a declared grid | Likely repair cost |
forecast |
One estimate per future step, up to 64 steps | Next-day traffic |
Scalar answers include p_null, the model’s probability that the input does not determine the value, and confidence. Estimates and forecasts include a median and an 80% interval from p10 to p90; applications can request all 99 quantiles with options.include_quantiles.
A practical Workers AI example
Suppose a support mailbox receives an order complaint:
Order R8-2048 arrived on October 17, 2026.
The monitor was $479.00 and shipping was $21.00.
The panel has a vertical line. Please replace or refund it.
A Worker can ask Clairic for only the values needed by the next step:
export interface Env {
  AI: Ai;
}

export default {
  async fetch(request, env): Promise<Response> {
    const state = await request.text();

    const result = await env.AI.run("@cf/cloudflare/clairic", {
      model: "clairic",
      state,
      reference_date: "2026-10-21",
      fields: {
        order_id: {
          type: "text",
          instructions: "Order number"
        },
        delivered_on: {
          type: "date",
          instructions: "Delivery date"
        },
        amount_paid: {
          type: "number",
          decimals: 2,
          unit: "USD",
          instructions: "Item price plus shipping"
        },
        damage: {
          type: "list",
          items: "text",
          instructions: "Each reported defect"
        }
      }
    });

    return Response.json(result);
  }
} satisfies ExportedHandler<Env>;
The shape follows Cloudflare’s documented Worker interface. It intentionally sets reference_date so relative or yearless dates do not silently depend on runtime context. For text fields, retain the returned span offsets: they let a reviewer highlight the exact evidence in the original message.
Validate the response before business logic
A typed model response still crosses a network and an evolving preview API. Validate the top-level object and every value your application will consume. During development, paste a sample response into Rubic8’s JSON Validator to catch syntax problems and use the JSON Formatter to inspect nested answers and usage fields. In production, enforce the same expectations in code with your normal schema library.
Also log truncated, token usage, model identifier, the field specification version, and your routing decision. Avoid storing raw documents or model responses if they contain data your retention policy does not permit.
Design confidence-aware automation
The most useful production feature is not merely valid types; it is the information available for routing uncertain cases. A safe pipeline should treat extraction and automation as separate decisions.
- Validate structure. Reject missing keys, unexpected types, non-finite numbers, and values outside business constraints.
- Check null probability. A high
p_nullmeans the document may not determine the field. - Check confidence and evidence. For exact text, verify spans point to the expected source. For dates and numbers, compare against domain rules.
- Route uncertainty. Send borderline cases to a human or a secondary process instead of silently filling the database.
- Measure outcomes. Sample accepted cases and label reviewed cases so thresholds reflect your documents, not intuition.
For example, a team might auto-accept an order ID only when the value is non-null, the span matches an approved ID pattern, p_null is below 0.02, and confidence is above 0.98. Those numbers are an illustrative policy, not Cloudflare guidance. The correct thresholds depend on error cost and must be calibrated against a labeled test set from your own workload.
Never treat a confidence score as a guarantee. Confidence can be miscalibrated on unfamiliar document layouts, languages, or image quality. Cloudflare specifically warns that intervals may be too narrow on out-of-distribution data.
Images, estimates, and forecasts need extra care
Clairic accepts up to four embedded images. The current docs list PNG, JPEG, and WebP, with a maximum of 4 MiB per image, 8 MiB decoded across images, and a 16 MiB request-body limit. Remote image URLs are not accepted. This makes receipts, screenshots, and photographed forms plausible inputs, but vision support does not remove the need to test blur, rotation, handwriting, small text, and multilingual layouts.
For estimates, define meaningful min, max, and step bounds. The p10–p90 range is more actionable than the median alone: a wide interval signals that the input provides weak evidence. Do not convert the median into a precise business fact.
Forecasting is the clearest preview limitation. Cloudflare says next-step forecasts follow recent patterns, while longer horizons tend to flatten toward the average and do not anticipate unseen events such as holidays. Clairic is not a replacement for a dedicated time-series model trained on your data. Use it for lightweight, bounded scenarios only after backtesting on the series you care about.
What does Clairic cost?
The current Workers AI pricing table lists Clairic at $0.10 per million input tokens, or 9,091 neurons per million input tokens. There is no output-token fee because the model does not generate output tokens.
At that unit price, a request using 20,000 input tokens would have a model-input charge of approximately $0.002:
20,000 / 1,000,000 × $0.10 = $0.002This is arithmetic based on the published unit price, not a measured bill. Actual input usage includes the state, field definitions, and image tokens, and other Cloudflare services in your architecture may have separate charges. Record the returned usage values and compare them with billing data before forecasting production spend.
A production pattern that limits blast radius
A sensible architecture uses each model only for the task it is good at:
- Receive and normalize the document without changing its meaning.
- Ask Clairic for the smallest useful set of typed fields.
- Validate the response and apply confidence, null-probability, span, and domain checks.
- Send uncertain cases to review; write accepted facts to a typed record with provenance.
- Run deterministic policy code or a decision model on those facts.
- Use an LLM only when the workflow needs explanation, drafting, or open-ended reasoning.
This separation reduces the amount of raw, potentially adversarial text that reaches an action-taking LLM. It also makes audits easier: you can inspect the source, extracted value, confidence signal, routing rule, and final action independently. That security benefit is an architectural inference, not proof that Clairic neutralizes prompt injection or eliminates model risk.
When to keep using an LLM or parser
Clairic is a strong candidate when inputs vary but outputs are naturally typed: invoice fields, order details, support-ticket facts, dates, totals, bounded estimates, or short forecasts. It is less appropriate when the main output is a nuanced explanation, summary, rewrite, or plan.
Keep deterministic parsers for stable machine-readable formats, checksums, and regulatory calculations. Cloudflare’s preview notes say one- and two-step arithmetic is reliable, but long dependent calculations and aggregations over many table rows are not yet. Extract the operands and calculate them in code.
Keep a capable LLM in the loop when understanding intent requires broad context or when the result must be natural language. A hybrid pipeline is often more defensible than replacing every component with the newest model.
Evaluation checklist
- Build a representative labeled set, including missing fields and ambiguous documents.
- Score each field separately; aggregate accuracy can hide a dangerous weak field.
- Track false acceptance, false rejection, null handling, and interval coverage.
- Test multiple languages, long inputs, corrupted files, and low-quality images relevant to your users.
- Version field instructions and reference dates alongside results.
- Stress-test latency, rate limits, concurrency, and regional behavior yourself.
- Re-run the suite before changing thresholds, field definitions, or preview model versions.
- Keep a human-review path for high-impact financial, legal, medical, or identity decisions.
Bottom line
Clairic is interesting because it narrows the model’s job. Instead of asking a general-purpose LLM to read, reason, format, and self-assess in one prompt, developers declare typed fields and receive values plus evidence and uncertainty signals. The preview price and input-only billing make it worth testing for high-volume extraction workloads.
The responsible interpretation is equally narrow: valid types are not verified facts, confidence is not certainty, and basic forecasting is not a specialized forecasting system. If your evaluation shows that Clairic performs well on your documents, a pipeline built around validation, confidence gates, provenance, and review can turn that narrow capability into reliable automation.
Official sources: Cloudflare’s October 19 announcement, model documentation, release changelog, and Workers AI pricing. Specs and pricing were checked on October 21, 2026 and may change during preview.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
