Cloudflare AI Crawler Controls: How to Block AI Training Without Blocking Google Search
A practical guide to Search, Training, and Agent controls, robots.txt, and protecting search access.
Yes: you can refuse AI training while keeping Google Search crawling available. Start with Search set to Allow, Training set to Disallow AI Training, and Bot Preference Sync enabled in Cloudflare. Choose an Agent policy separately. Do not substitute Training: Block without reviewing its effect on mixed-use crawlers.
This is a crawl-policy recommendation, not a promise of rankings, AI citations, traffic, or advertising revenue. Keeping a door open does not guarantee that a search engine will index a page or send visitors.
Fact-checked September 28, 2026. Cloudflare's September 15 update changes the meaning of earlier AI-blocking guidance; check the date of any tutorial you follow.
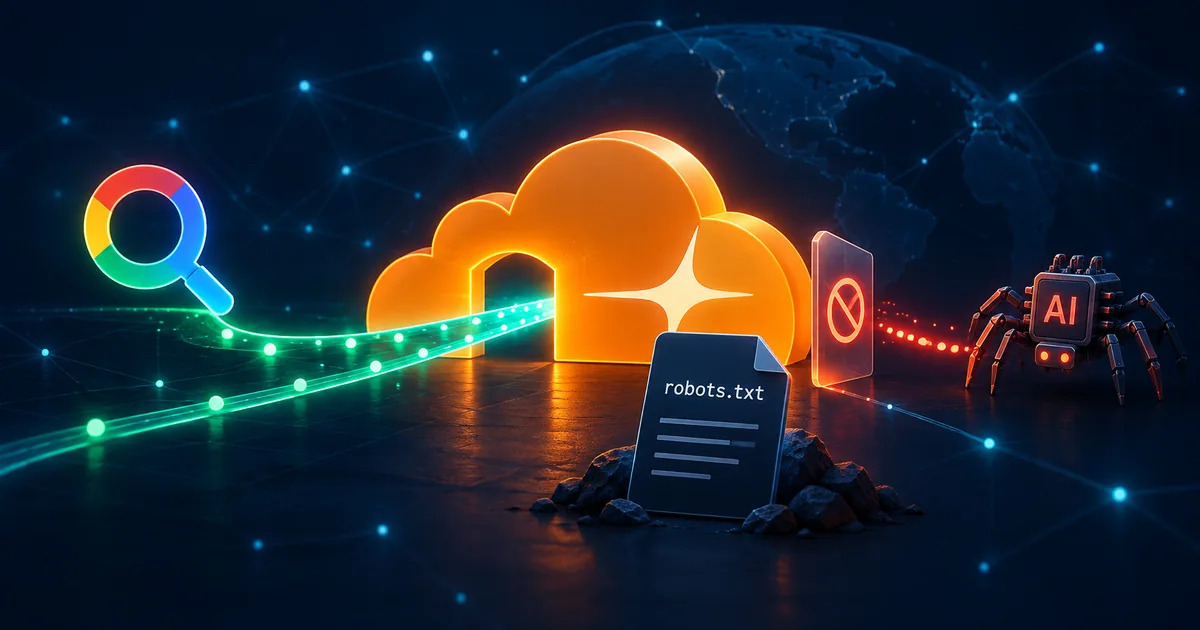
Search crawlers, AI training crawlers, and agents
The useful question is not simply whether a request comes from a bot. It is what the operator intends to do with your content. Cloudflare's behavior-based controls separate three uses:
- Search: collecting material for an index that can help people discover information later.
- Training: gathering material to train or fine-tune models.
- Agent: accessing a page in response to a person's current task, such as an assistant fetching a link.
One crawler can serve multiple purposes. A company name, a user-agent string, and a use category are therefore different things. Blocking a company's entire traffic may remove a discovery channel you wanted to keep.
For a publisher, these distinctions create three separate editorial decisions: who may help readers find the site, who may use its work for training, and who may fetch it for an individual user. Write those decisions down before opening a security dashboard. Otherwise, a broad “AI” label can turn a narrow content preference into an unintended access restriction.
What changed in Cloudflare's crawler controls?
Cloudflare introduced Search, Training, and Agent controls in July 2026. Its September 15 announcement added Disallow AI Training: publish applicable training preferences through Bot Preference Sync, preserve search access for Accountable mixed-use crawlers, and block other training crawlers. Training Block and Block on pages with ads now also cover mixed-use crawlers, including Googlebot, Bingbot, and Applebot.
“Accountable” includes existing capabilities and commitments still being developed. A significant limitation: Cloudflare says Bing's robots.txt training opt-out is targeted for early 2027; until then, this setting does not automatically communicate that preference to Bing. Review the operator-specific controls instead of assuming universal coverage.
Cloudflare also describes migration from its legacy settings. For an existing site, inspect the resulting configuration rather than assuming either that nothing changed or that every earlier block became more restrictive. The current dashboard and recent request logs are your evidence.
Disallow AI Training versus Block
The distinction is content-use preference versus broader access denial. Disallow AI Training combines a robots.txt preference with selective enforcement. Block denies access to the affected crawler category, even where a crawler also supports search. Allow is not an exemption from other security rules.
For an ad-supported publisher seeking discovery, our starting recommendation is Search: Allow; Training: Disallow AI Training; Bot Preference Sync: enabled. Treat Agent: Block on pages with ads as a business choice to evaluate, not an automatic SEO improvement. This aligns with the ad-supported preset described in Cloudflare's announcement.
A tool website may reasonably make a different agent decision. An assistant checking documentation can help a future user understand a tool, while a task performed entirely off-site may produce no visit. Compare actual outcomes before choosing a blanket agent restriction. Neither choice establishes how much revenue you will gain or lose.
How a wrong configuration can hurt Google Search
A search-friendly robots.txt file cannot rescue a request denied before it reaches the website. Review the whole request path: Cloudflare policy, custom WAF rules, hosting firewall, application permissions, and the response delivered by the site.
Consider a fictional publisher that changes its training setting, then sees a sharp increase in denied Googlebot requests. The right first step is to inspect matching security events and reverse the unintended restriction. Rewriting articles or requesting indexing while access remains blocked does not address that failure.
Also avoid applying this rule to content you want crawled:
User-agent: Googlebot
Disallow: /
A wildcard group with the same Disallow line can create a similar problem. Google explains that robots.txt manages crawling, not guaranteed removal from search results. A disallowed URL may still appear without its content being crawled. That possibility is not a healthy visibility strategy.
Do not use noindex as an AI-training opt-out on pages meant to rank. It addresses a different objective. Likewise, changing the visible user-agent in a test request does not authenticate the request as Googlebot. Use Google's crawler verification methods, which include reverse and forward DNS checks or matching published IP ranges.
Google-Extended is different from Googlebot
Google's crawler documentation identifies Google-Extended as a robots.txt product token, not a separate HTTP user agent. It controls specified uses for future Gemini training and grounding in Gemini Apps and Vertex AI. Google states that it does not affect inclusion or ranking in Google Search.
That scope matters: Google-Extended is not a universal “disable every Google AI feature” switch. For AI Overviews and AI Mode, consult Google Search Central's AI features guidance. Googlebot access, indexing eligibility, and preview controls are distinct from the Google-Extended preference.
Keep a short change record that states your actual objective. “Refuse the uses governed by Google-Extended while retaining search access” is testable. “Turn off AI” is too ambiguous to validate and too easy for another administrator to misinterpret.
GPTBot, OAI-SearchBot, and ChatGPT-User
OpenAI's crawler documentation separates these identities:
- GPTBot: crawls material that may be used to train OpenAI's generative foundation models.
- OAI-SearchBot: supports discovery in ChatGPT search.
- ChatGPT-User: fetches pages for certain user-initiated actions; it is not the automatic search crawler, and robots.txt may not apply to those actions.
OpenAI documents that OAI-SearchBot and GPTBot preferences are independent. You can permit search while disallowing training. Search changes may take approximately 24 hours to be reflected. Access does not guarantee inclusion or citation.
For implementation, keep your OpenAI decision separate from your Google decision. Test the names individually rather than entering every crawler into a single shared group with identical rules. Also check the operator's published IP information when evaluating real traffic; a familiar name in a log is not sufficient proof of identity.
How robots.txt fits with Bot Preference Sync
Cloudflare's Bot Preference Sync aligns the robots.txt served at the edge with bot preferences. This makes the file a relevant part of the configuration even when the main decisions happen in the dashboard.
Inspect the public response after making changes. The copy in your hosting file manager may not be the complete response a crawler receives through Cloudflare. Preserve existing path restrictions and sitemap declarations unless you deliberately intend to change them.
The following is an illustrative policy fragment, not a replacement for an existing file:
# Append only after reviewing existing groups.
User-agent: GPTBot
Disallow: /

User-agent: Google-Extended
Disallow: /
These groups express two specific preferences; they do not prove that Googlebot or OAI-SearchBot is allowed elsewhere. Review existing specific and wildcard groups too. Avoid adding a blanket Allow for a named search crawler without understanding whether that bypasses restrictions you still need.
Google's robots.txt creation guide explains file placement and group structure. Serve the file at the root of the relevant host, and check each host you actually use. A working file on one hostname is not proof that another hostname has the same policy.
Use Rubic8's Robots.txt Generator & Tester to prepare and test directives. Its generator applies the same rules to all user-agents entered in the main user-agent field. Do not put GPTBot and Googlebot together there if you intend to treat them differently. Review separate groups in the finished file and test representative paths for each crawler.
A robots.txt test is only one layer of evidence. It cannot certify Cloudflare enforcement, operator compliance, historical training use, or search inclusion. Keep restricted information behind proper access controls; robots.txt is publicly readable and is not authentication.
A practical setup for a publisher, blog, or tool site
1. Define what you need to preserve
List your main organic landing pages, popular tools, recent articles, essential images, and supporting assets. Include pages with ads and pages without them. Record the current crawl policy and a baseline of search traffic before changing anything.
Assign one person responsibility for the rollout and rollback. For a small site, this can be a simple dated note: which setting changed, why, what URLs were tested, and what would trigger reversal.
2. Confirm Cloudflare is in the request path
Cloudflare's AI Crawl Control setup guide requires the domain's traffic to be proxied through Cloudflare. Merely using Cloudflare DNS does not establish that its edge is enforcing these controls for every hostname.
Open the relevant domain's security settings and inspect its AI bot policies. Dashboard wording can evolve, so verify the displayed behavior rather than following an old screenshot blindly. Keep a copy of the current settings for comparison.
3. Make one deliberate policy change
Apply the search-preserving starting policy described above, then inspect the served robots.txt and requests before broadening restrictions. If your organization wants agents restricted only on advertising pages, test both an article that displays ads and a tool page that does not.
Review existing crawler-specific blocks as well. AI Crawl Control's crawler management documentation explains individual allow/block actions and their relationship with WAF rules. A category-level intention and a separate custom rule can conflict.
4. Validate before calling the change successful
Choose a compact set of representative URLs and record expected results before testing. For example: an evergreen article should remain fetchable by search; GPTBot should match the training restriction; the homepage should load normally for a reader.
Keep both successful and failed observations. A single successful homepage request is not evidence that a deep article, an image, or a second hostname works. If you cannot verify a result, label it unverified rather than treating the absence of an error report as success.
Post-configuration checklist
- Public robots.txt: fetch the actual HTTPS response and compare it with the intended policy. Check unexpected broad exclusions.
- Search access: inspect real crawler security events and use Search Console's live URL inspection for representative pages.
- Response content: confirm that an apparently successful response contains the article, not a challenge, login screen, or error message.
- Resources: check important images, styles, and scripts alongside the HTML.
- Indexing signals: inspect robots meta tags, X-Robots-Tag headers, canonical URLs, and sitemap entries.
- Training preferences: test the relevant user-agent groups and inspect enforcement logs where available.
- Agent policy: test affected pages separately; confirm the decision fits the site's intended user experience.
- Measurement: annotate the change date and compare crawl errors, impressions, clicks, referral visits, and revenue over an appropriate period.
- Rollback: restore the prior setting if verified search traffic is unintentionally denied, then investigate the matching rule.
Rubic8's SEO & AI Visibility Checker can support page-level checks of metadata and related signals. Treat its results as diagnostics, alongside Cloudflare logs and Search Console, rather than proof that a particular search engine will rank the page.
What this means for SEO, GEO, AEO, and AdSense
Our recommendation is to protect access first and evaluate discovery second. SEO, generative engine optimization (GEO), and answer engine optimization (AEO) all benefit from a clearly stated content strategy, but none turns a crawler setting into a ranking guarantee.
For this site model, publish explanations readers can verify, answer the main question early, cite original documentation, and connect articles to useful tools. Rubic8's Entity SEO & E-E-A-T guide provides related reading on identity and trust. The llms.txt and AI SEO article discusses why an additional text file should not distract from crawlability and useful content.
Google's AI guidance says no special AI markup or additional machine-readable file is required for its AI search features. Adding a file or schema solely because it sounds “AI-ready” is therefore not a substitute for making your real pages accessible and helpful.
For AdSense, use a measurement plan rather than a revenue prediction. Record human sessions and page revenue alongside crawler activity. Fewer automated requests do not, by themselves, demonstrate more monetized visits. A traffic change can also reflect seasonality, rankings, demand, or other site changes. Avoid assigning causation to the crawler policy without supporting evidence.
Frequently asked questions
Can I block AI training without blocking Google Search?
Yes, within the scope of the available operator controls. Follow the search-preserving configuration above, review existing rules, and verify real access. Do not interpret it as a universal guarantee about every AI company or use.
Is Disallow AI Training just a robots.txt rule?
No. It combines published preferences and selective blocking. See the distinction above; checking only the file leaves the enforcement layer untested.
Should I block all AI agents on an advertising website?
That is a business decision. Begin with a clear objective, review actual agent activity and referrals, and test the effects on readers' workflows. An ad-supported site and a public documentation tool may reasonably choose different policies.
Does blocking GPTBot remove my site from ChatGPT search?
GPTBot is the training control; OAI-SearchBot is the separate search control. Review both and avoid an unrelated firewall rule that denies the search crawler as well.
Does changing robots.txt erase past training data?
Do not assume that it does. This guide concerns access and usage preferences going forward; it does not establish a mechanism for removing information from already trained models.
Will this increase rankings or AdSense earnings?
No increase is guaranteed. The immediate goal is an accurately implemented policy that preserves intended discovery access. Evaluate later traffic and revenue changes against your baseline.
Next step: audit the robots.txt your site actually serves with the Robots.txt Generator & Tester, then verify the same URLs through your security logs and search tools.
