Google Indexing API Quotas: What Changed in October 2026
Current limits, eligible page types, batch behavior, and safe implementation after Google removed the old quota form
Google quietly changed an important piece of Indexing API documentation on October 16, 2026. The Search Central documentation update log says the quota page was revised to explain the current quotas and process, and that an outdated request form was removed. That matters because older tutorials still tell site owners to request approval or a larger quota before using the API.
The current rules are simpler, but also stricter than many SEO shortcuts imply. The API is free, the default publish quota is 200 requests per day per project, and its supported use cases remain limited to pages with JobPosting structured data or BroadcastEvent embedded in a VideoObject. It is not a general “instant indexing” endpoint for articles, products, category pages, or every URL in a sitemap.
This guide separates Google’s published facts from implementation advice. It shows how to budget requests, send an update, inspect notification metadata, handle errors, and decide when the Indexing API is the wrong tool.
What changed on October 16, 2026?
Published fact: Google’s Search documentation updates log records an Indexing API quota documentation change on October 16, 2026. Google says it updated the quota page to reflect the current quotas and process and removed an outdated form.
The live quota and pricing page now lists the default limits and directs users to the Google API Console to view project quota. It does not link to the old Indexing API quota request form.
Practical interpretation: Treat any tutorial that makes quota approval a required setup step as stale. Start with the published default limits and verify the Quotas page for your own Google Cloud project. Do not build capacity plans around an assumed increase.
Current Google Indexing API quotas
Google currently publishes these per-project defaults:
| Quota | Current limit | What it controls |
|---|---|---|
| Publish requests | 200 per day | Update or deletion notifications sent with the publish method |
| Metadata requests | 180 per minute | Checks for the last notification Google received for a URL |
| All requests | 380 per minute | Combined request rate across Indexing API methods |
The daily quota resets at midnight Pacific Time. Google also states that there is no charge for using the Indexing API. Quotas apply per Google Cloud project, not per service account or per website.
A batch reduces network connections but does not multiply quota. If one multipart request contains 75 URL notifications, Google counts 75 requests against the daily publish quota—not one.
A small capacity calculation
With the default publish quota, the maximum theoretical notification budget is 200 URL events per day. An update and a later deletion are two events. A site that publishes 120 job pages and removes 100 expired jobs on the same day would need 220 publish requests, so it would exceed the default daily limit.
| Daily activity | Publish requests | Fits the default? |
|---|---|---|
| 80 new jobs + 40 updates + 30 removals | 150 | Yes, with 50 requests of headroom |
| 120 new jobs + 100 removals | 220 | No |
| Four batches of 50 notifications | 200 | Yes; batches still count per URL |
Rubic8 recommendation: reserve part of the daily budget for corrections and removals. A queue capped below 200 is safer than sending 200 scheduled updates early in the day and leaving no capacity for urgent deletions. The exact reserve should reflect your publishing pattern; Google does not prescribe one.
Who can use the Indexing API?
Google’s usage guide says the Indexing API can only be used for pages containing one of these supported structured-data types:
JobPostingfor job vacancy pages.BroadcastEventembedded in aVideoObjectfor livestream pages.
The words “can only be used” are the important part. A news article, product page, profile, documentation page, local landing page, or ordinary prerecorded video does not become eligible merely because it changes frequently.
For unsupported URLs, use normal discovery and crawling mechanisms: internally link the page, include canonical URLs in XML sitemaps, return clean HTTP responses, and avoid blocking important resources. Rubic8’s Robots.txt Generator & Tester can help review directive logic, while the SEO & AI Visibility Checker can inspect several public page signals. Neither tool can force Google to crawl or index a URL.
What a successful API response actually means
A successful publish request means Google accepted the notification. It does not guarantee that Google indexed the URL, retained it in the index, ranked it, or displayed its rich result.
Google describes the API as a way to notify it about additions, updates, and removals so it can schedule a fresh crawl. Google’s metadata endpoint reports the last update or removal notification received for a URL. The documentation explicitly says this status does not tell you when Google indexed or removed the page.
Keep three states separate in logs and dashboards:
- Notification accepted: the API returned HTTP 200.
- Page crawled: Googlebot fetched the URL, observable in server logs or other Google tools.
- Page indexed: Google selected the page for its index, which is a separate decision.
Calling all three “indexed” creates false success metrics and makes troubleshooting harder.
Setup checklist before sending requests
Google’s quickstart and prerequisites require a Google Cloud project, the Indexing API enabled for that project, a service account, Search Console ownership, and an OAuth access token.
- Create or select a Google Cloud project.
- Enable the Indexing API.
- Create a service account and obtain credentials through Google’s supported flow.
- Add the service-account email as a verified owner of the relevant Search Console property.
- Request an OAuth token with the Indexing API scope.
- Verify that each submitted URL belongs to the owned property and carries eligible structured data.
Do not put service-account private keys in a public repository, browser-side JavaScript, a CMS field, or an online formatting tool. Store secrets in an appropriate secret manager and rotate exposed credentials.
Send an update notification
The publish endpoint is:
POST https://indexing.googleapis.com/v3/urlNotifications:publishThe request must use Content-Type: application/json. A minimal curl example is:
curl -X POST \
  "https://indexing.googleapis.com/v3/urlNotifications:publish" \
  -H "Authorization: Bearer ACCESS_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
    "url": "https://example.com/jobs/platform-engineer",
    "type": "URL_UPDATED"
  }'
Use URL_UPDATED when an eligible page is new or materially updated. Use URL_DELETED after the page has been removed from your server. Do not use deletion notifications merely because a job is temporarily unavailable if the page still represents a valid, accessible vacancy; align API events with the page’s real lifecycle and applicable structured-data guidelines.
You can paste a sanitized request body into Rubic8’s JSON Formatter for readability or the JSON Validator to catch syntax errors. Remove access tokens, private URLs, personal data, and proprietary fields first. Valid JSON does not prove that the URL is eligible or that the authenticated account owns it.
Check the last notification received
To retrieve notification metadata, URL-encode the page URL and send a GET request:
curl \
  -H "Authorization: Bearer ACCESS_TOKEN" \
  "https://indexing.googleapis.com/v3/urlNotifications/metadata?url=https%3A%2F%2Fexample.com%2Fjobs%2Fplatform-engineer"
A successful response can include latest_update and latest_remove timestamps. These are receipts for notifications—not crawl times and not index-status checks. Rubic8’s URL Encode tool can help test a sanitized URL parameter, but application code should use the standard URL-encoding function supplied by its language or runtime.
Batching: fewer connections, same quota cost
Google permits up to 100 calls in one multipart batch sent to https://indexing.googleapis.com/batch. This can reduce connection overhead and simplify high-throughput delivery, but every URL still consumes its own quota unit.
Batch responses also contain a separate result for each part. Do not treat one successful outer HTTP exchange as proof that every URL notification succeeded. Parse each response part, record its status, and retry only the failed items when appropriate.
Rubic8 recommendation: use modest batch sizes and attach an internal idempotency key to each queue record. The API does not require that application-level key; it is an operational technique that helps prevent accidental duplicate sends when a worker crashes after receiving a response.
Error handling that protects quota
Google’s Indexing API error list documents these especially useful cases:
| Status | Typical meaning | Recommended response |
|---|---|---|
| 400 | Missing or invalid URL, or an unsupported notification type | Fix the payload; do not retry unchanged |
| 401 | Missing, invalid, or expired authorization credentials | Refresh authentication and retry after validation |
| 403 | Ownership could not be verified, API is not configured, or access is forbidden | Check Search Console ownership and project configuration |
| 429 | Rate or quota limit exceeded | Stop sending, respect the limit, and resume with backoff |
| 500/503 | Temporary server-side failure | Retry with exponential backoff and jitter |
Google notes that rejected requests do not cause it to crawl the URL. For a 429 response containing Insufficient tokens for quota 'indexing.googleapis.com/default_requests', repeatedly retrying immediately only increases noise. Persist the event and schedule it after the relevant quota window resets.
A production-safe queue pattern
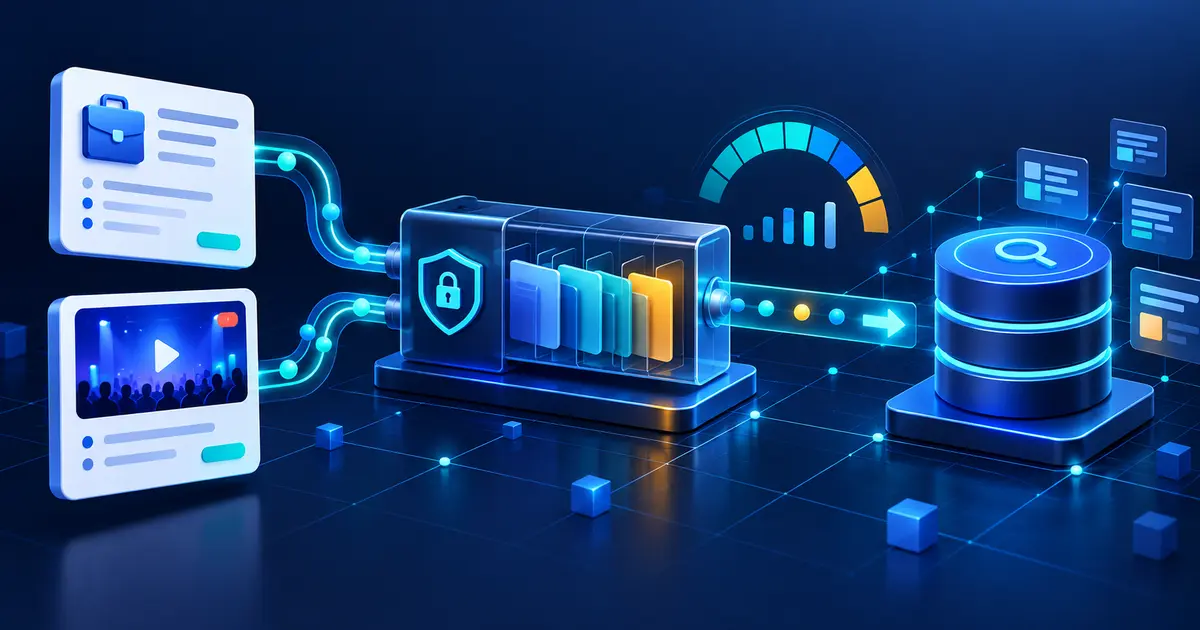
A small event-driven pipeline is easier to audit than direct API calls scattered through a CMS:
- The publishing system emits a job-page or livestream lifecycle event.
- A validator confirms the canonical URL, ownership scope, event type, and eligible structured data.
- A queue deduplicates equivalent pending events and assigns priority.
- A worker checks the remaining daily and per-minute budget before sending.
- The worker stores the request time, response code, response body, and retry state.
- Monitoring keeps API acceptance, crawling, and indexing as separate metrics.
Prioritize deletions and time-sensitive livestream changes over routine resubmissions. Avoid notifying Google every time an unrelated field changes. A request budget should represent meaningful page lifecycle changes, not act as a substitute for a clean crawlable site.
Common mistakes to avoid
- Submitting unsupported page types: the API is not a shortcut for general SEO indexing.
- Counting a batch as one request: quota is charged per URL call.
- Equating HTTP 200 with indexing: it confirms receipt of the notification.
- Polling metadata as an index checker: it returns notification history, not index state.
- Using multiple projects or accounts to evade limits: Google explicitly warns that attempts to circumvent quotas can result in access being revoked.
- Exposing credentials: service-account secrets do not belong in frontend code or online utilities.
- Following the old quota form workflow: Google removed that outdated form from the current documentation.
Decision checklist
Use the Indexing API only when every answer below is yes:
- Is the URL a job posting or a livestream page with the required supported structured data?
- Do you control and verify the relevant Search Console property?
- Can the project stay within 200 publish requests per day and the minute-level limits?
- Can your system protect OAuth credentials and log each notification result?
- Does your team understand that acceptance is not an indexing guarantee?
If any answer is no, improve ordinary discovery, technical SEO, and page quality instead of forcing the API into an unsupported workflow.
Bottom line
The October 16 documentation update removes a misleading setup artifact, but it does not turn the Indexing API into a general indexing tool. The dependable implementation is narrow: eligible job or livestream pages, verified ownership, authenticated notifications, a 200-per-day publish budget, per-URL batch accounting, and monitoring that never confuses notification receipt with an indexed result.
Build around those constraints and the API can keep short-lived eligible content fresher. Ignore them and the likely outcomes are wasted quota, misleading dashboards, and avoidable access risk.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
