Gemini Model Routing: Cut AI Agent Cost per Successful Task
A practical guide to cheap classifiers, thinking levels, caching tradeoffs, and measuring cost per task done right
AI API prices keep falling, yet the total bill for autonomous agents can still rise. The reason is simple: an agent rarely makes one model call and stops. It loops, retries, invokes tools, carries context forward, and may spend reasoning tokens on decisions that did not need deep reasoning in the first place.
On November 3, 2026, Google published a useful engineering pattern for this problem: measure cost per successful task, then route routine work to a cheaper path and escalate only tasks that actually need more reasoning.
The idea is broader than one benchmark or one classifier. The production question is not “Which model has the lowest price per million tokens?” It is:
How much do we spend, end to end, for each task that passes our real verification criteria?
This guide turns that idea into a practical routing architecture for Gemini agents. It explains where a router can save money, where it can make things worse, why maxOutputTokens is not a thinking-budget control, how context caching changes the economics, and what to log before you trust a routing strategy in production.
Verification note: product details and current Gemini pricing were checked against Google documentation on November 5, 2026. Benchmark observations attributed to Google are vendor-reported, single-run experimental results, not independent Rubic8 benchmarks. The rollout framework, formulas, examples, and operational recommendations below are Rubic8 analysis.
Why “Cost per Successful Task” Is the Better Metric
Token price is only one component of an agent's real cost. A production task can include:
- the initial model request;
- internal thinking tokens;
- tool calls and external API charges;
- repeated context;
- retries after malformed output or failed tools;
- validation or grading calls;
- a fallback to a stronger model;
- and human review when automation fails.
A simple operating metric is:
cost_per_successful_task =
    total_router_cost
  + total_model_cost
  + total_tool_cost
  + total_retry_cost
  + total_validation_cost
  --------------------------------
        successful_tasks
The exact accounting model can vary by application, but the denominator matters. A strategy that is cheap because it fails more often may be more expensive per successful outcome than a strategy with a higher raw API bill.
An illustrative example
Imagine two routing strategies processing the same 100 tasks:
| Strategy | Total spend | Tasks passing verification | Cost per successful task |
|---|---|---|---|
| Cheap-first router | $0.55 | 80 | $0.006875 |
| Better classifier + fallback | $0.62 | 96 | $0.006458 |
These numbers are hypothetical, not a benchmark. They illustrate why optimizing the numerator alone can produce the wrong decision.
What Google Tested on November 3
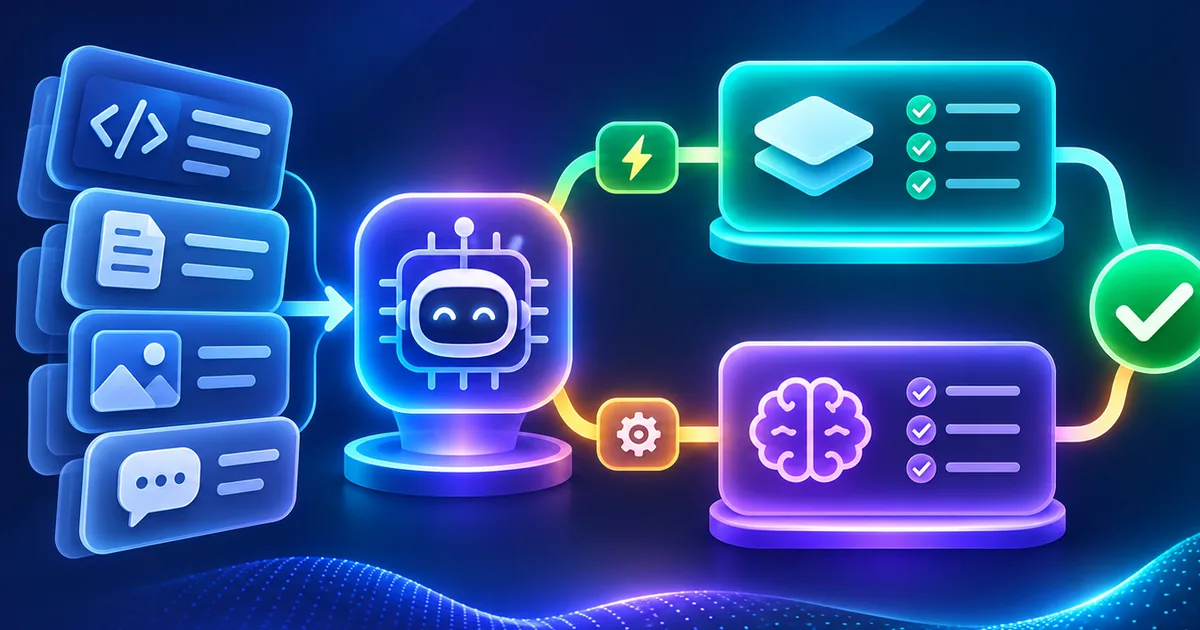
Google's engineering article placed a lightweight classifier in front of Gemini model calls and used it to decide whether a coding-agent task should take a cheap path or a stronger reasoning path.
The article used TypeSafe's Jev classifier as one example and explicitly stated that Google has no partnership with TypeSafe and was not endorsing the product. Google also pointed to DiffusionGemma as a Google-native, open-weights alternative for similar discriminative routing patterns.
The experiment used a small 50-question coding-agent suite, automatic grading, hand-assigned task difficulty, and one run per setup. Google reported that a classifier-based router generalized better to held-out tasks than a frozen keyword-and-length heuristic, and that routing simple tasks to Flash-Lite while escalating harder ones to Gemini 3.8 Flash at low thinking could match the successful-task result of the strongest non-router baseline in that test.
Those findings are useful design evidence, but the limitations matter just as much. A 50-task experiment does not prove that the same threshold, classifier, or model pair will optimize your workload.
Primary source: Google Developers Blog: Cost per task — using cheap classifiers to route across Gemini models and thinking levels.
Rule 1: Start With a Cheaper Configuration Before Building a Router
A router adds another service, another decision, another failure mode, and usually another network hop. Do not add it until you know a simpler configuration cannot already meet your quality target.
Google's strongest no-router setup in its small experiment was Gemini 3.8 Flash with the thinking level set to low. That configuration solved all tasks in the published suite. Google's first recommendation was therefore to start with a fast model on a lighter thinking setting and add routing only when the workload provides a real reason.
That leads to a practical baseline process:
- Choose one model that is capable enough for most tasks.
- Set the lowest thinking level that still meets your verification target.
- Run a representative evaluation set.
- Measure success rate, end-to-end latency, thinking tokens, retries, and cost.
- Only then test whether a router improves the result.
If one light configuration already passes nearly every task, a routing layer may add complexity without meaningful savings.
Rule 2: Do Not Use maxOutputTokens as a Thinking-Budget Dial
One of the most practical lessons in Google's November 3 article is that maxOutputTokens is a ceiling on generated output, not a reliable way to tell a reasoning model to think less.
In Google's experiment, cutting the output ceiling did not meaningfully reduce thinking on easy tasks. On harder tasks, the tighter cap caused failures because the model ran out of room before completing the work.
If your Gemini model supports configurable thinking levels, control reasoning with the thinking configuration itself.
A current Python pattern for Gemini Flash looks like this:
from google import genai
from google.genai import types

client = genai.Client()

response = client.models.generate_content(
    model="gemini-3.8-flash",
    contents="Check this deployment plan for one concrete race condition.",
    config=types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(
            thinking_level="low"
        )
    )
)

print(response.text)
Use output limits to bound output length when that is a product requirement. Use thinking controls to tune reasoning effort.
Current Gemini Pricing Changes the Routing Math
As of November 5, 2026, Google's published Standard pricing lists Gemini 3.5 Flash-Lite at $0.30 per million input tokens and $2.50 per million output tokens, with output pricing including thinking tokens.
Gemini 3.8 Flash currently has introductory Standard pricing of $0.75 per million input tokens and $3.75 per million output tokens through December 31, 2026. Google's pricing page lists higher rates beginning January 1, 2027.
| Model | Current Standard input / 1M | Current Standard output / 1M | Typical routing role |
|---|---|---|---|
gemini-3.5-flash-lite |
$0.30 | $2.50 | High-volume simple tasks and low-cost first path |
gemini-3.8-flash |
$0.75 through Dec. 31, 2026 | $3.75 through Dec. 31, 2026 | Harder agentic tasks; configurable thinking |
These prices are useful inputs, but they still do not tell you the cost of a successful task. The harder path may use more thinking tokens, but the cheap path may create retries or escalation calls. Measure both.
Pricing source: Gemini Developer API pricing.
A fair token-cost comparison
If both models hypothetically receive exactly 10,000 input tokens and produce exactly 1,000 billable output tokens, the current token charge would be:
- Gemini 3.5 Flash-Lite: 10,000 × $0.30/M + 1,000 × $2.50/M = $0.0055.
- Gemini 3.8 Flash: 10,000 × $0.75/M + 1,000 × $3.75/M = $0.01125 at the current introductory rate.
This is arithmetic using equal token counts, not a prediction of real task cost. Real output may include different amounts of thinking, and a failed cheap attempt followed by escalation can cost more than one successful Flash request.
Rule 3: Route on an Atomic Signal, Not a Vague “Easy or Hard” Guess
Broad difficulty labels sound convenient but often hide several unrelated factors. A task can be short yet require multi-step state simulation. Another task can be long because it includes a large log file but require only one direct extraction.
A better router asks one narrow question at a time.
For example:
Does this task require more than one sequential calculation,
simulation step, or logical deduction to produce the answer?
That is easier to calibrate than asking a classifier to decide whether the entire request is “simple” or “complex.”
Depending on your application, other atomic signals might be:
- Does the task require modifying more than one file?
- Does the answer depend on state produced by a previous step?
- Does the request require a tool call before the final answer can be known?
- Does the task contain an irreversible action?
- Does the output require a security-sensitive judgment?
Do not combine all five into one opaque complexity score until you have evidence that the score is stable on held-out traffic.
Why Regex and Prompt-Length Routers Usually Age Badly
A local heuristic such as “prompts over 35 words go to the expensive model” is attractive because it is free and deterministic. It is also easy to overfit.
Long inputs can contain trivial extraction tasks. Very short prompts can hide difficult state traces, language edge cases, or multi-step math. Keyword lists have the same problem: they recognize vocabulary, not reasoning structure.
If you do use a heuristic router, treat it like a model:
- freeze the rules before evaluating;
- test on held-out tasks;
- track false cheap routes and unnecessary escalations separately;
- version every rule change;
- and keep a fallback when the rule is uncertain.
Google's November experiment is a good reminder that a heuristic can look excellent on the examples used to design it and weaken quickly when unseen tasks arrive.
A Practical Two-Path Router
The simplest useful architecture has three parts:
- A lightweight classifier estimates whether the task requires multi-step reasoning.
- Simple tasks go to Gemini 3.5 Flash-Lite.
- Tasks above the escalation threshold go to Gemini 3.8 Flash with
lowthinking.
Application-side pseudocode:
def choose_route(task):
    probability = classify_multi_step(task)

    if probability < 0.65:
        return {
            "model": "gemini-3.5-flash-lite",
            "thinking_level": None
        }

    return {
        "model": "gemini-3.8-flash",
        "thinking_level": "low"
    }
The 0.65 threshold is illustrative. Do not copy it blindly. Calibrate thresholds against your own false-negative cost. Routing a hard task to the cheap path may be harmless for log parsing and unacceptable for an automated infrastructure change.
Validate the Output Before You Call a Route “Successful”
The router's objective should not be “the API returned HTTP 200.” It should be “the task passed the required checks.”
For structured agent tasks, verification can include:
- valid JSON or schema conformance;
- required fields present;
- tool arguments within allowed ranges;
- unit tests or static checks passing;
- expected files changed and unrelated files untouched;
- citations present when evidence is required;
- human approval for high-impact actions.
When inspecting sanitized JSON fixtures during development, Rubic8's JSON Formatter can make payloads easier to read and the JSON Validator can catch syntax problems. Remove secrets, personal information, proprietary prompts, and internal URLs before pasting data into any browser-based tool.
Caching Can Reverse the Economics of Routing
Routing looks most attractive when tasks are short and self-contained. Long-running coding agents often carry a large repeated prefix: repository maps, tool definitions, policies, memory, or reference documents.
Google notes that context caching can substantially reduce the cost of resending repeated context, but a cache is associated with a model. If your router switches models frequently, you may need separate caches or lose part of the benefit.
That creates a useful operational split:
- Route short, independent tasks such as schema checks, log extraction, small classifications, or isolated code questions.
- Keep long, context-heavy conversations on one model when cache reuse is a major part of the cost advantage.
Before introducing routing into a large-context agent, compare the money saved by cheaper inference with the cache discount you may be giving up.
What to Log for Cost-per-Task Analysis
A routing strategy is difficult to improve if all you store is the final model name.
For each task, consider recording safe operational fields such as:
{
  "task_type": "schema_check",
  "router_version": "2026-11-05-a",
  "route": "cheap",
  "model": "gemini-3.5-flash-lite",
  "thinking_level": null,
  "input_tokens": 8200,
  "output_tokens": 640,
  "retry_count": 0,
  "tool_calls": 1,
  "validation_passed": true,
  "latency_ms": 910,
  "estimated_cost_usd": 0.0041
}
Do not log raw prompts, secrets, personal data, or full tool payloads simply to improve cost reporting. Aggregate what you can, redact what you must, and keep request identifiers so incidents can be investigated through controlled systems.
The most useful dashboard usually includes:
- cost per successful task by task type;
- cheap-path success rate;
- escalation rate;
- false cheap routes;
- unnecessary escalations;
- retry rate;
- p50 and p95 end-to-end latency;
- thinking tokens by route;
- cache hit rate;
- tool cost and model cost separately.
When a Router Is Probably Not Worth It
Skip the router, at least initially, when:
- one light model configuration already passes almost every task;
- traffic volume is too small for the savings to justify another service;
- most turns reuse a large model-specific cache;
- classification latency is significant relative to the task itself;
- the cost of a wrong cheap route is high;
- your team does not yet have reliable task-level verification.
In these cases, tuning thinking level, batching, caching, or prompt structure can be a simpler optimization.
When Routing Is a Strong Candidate
A router becomes more attractive when the workload contains a large, repeatable mix of clearly different task classes:
- simple extraction mixed with multi-step reasoning;
- format checks mixed with code debugging;
- routine triage mixed with expensive remediation planning;
- high-volume subagent tasks mixed with occasional deep analysis;
- short standalone requests where cross-model caching is not important.
The larger and more stable the difference between the cheap-path workload and escalation workload, the easier it is to justify and validate routing.
A 30-Minute Routing Audit
- Pull 50–100 recent tasks. Redact sensitive content and preserve the true distribution of task types.
- Write a verification rule for each task type. A route is successful only if the output passes it.
- Run Gemini 3.8 Flash at low thinking as the baseline. Record success, latency, tokens, retries, and cost.
- Run the cheap candidate. Measure where Flash-Lite fails, not just average cost.
- Define one atomic escalation signal. Avoid a vague “hard vs easy” prompt.
- Freeze the router. Evaluate on held-out tasks that were not used to design the rule.
- Include cache effects. Repeat the test with realistic context sizes.
- Compare cost per successful task. Include router, model, tool, retry, and validation spend.
If the router only wins on the development examples and not on held-out traffic, do not ship it.
How This Fits the Current Gemini Migration
Rubic8's Gemini API migration guide covers moving deprecated Flash identifiers to current replacements. Routing is the next optimization layer after that migration is stable.
First make the effective model explicit, fix incompatible request parameters, and verify correctness. Then optimize which tasks should reach which model and thinking level. Mixing a migration and a routing redesign in the same rollout makes regressions harder to diagnose.
Should Rubic8 Build a Cost-per-Task Calculator?
This trend suggests a useful future Rubic8 developer tool: a calculator that accepts model token rates, average input/output tokens, router cost, escalation rate, retries, tool charges, and success rate, then compares strategies by cost per successful task.
That would be more useful than a basic token calculator for agent systems because it includes the operational denominator that actually matters. This article does not link to such a tool because Rubic8 does not currently expose one at a verified public URL.
Production Checklist
- Define “success” before optimizing cost.
- Baseline the cheapest single-model configuration that meets quality requirements.
- Control reasoning with thinking level, not an arbitrary output cap.
- Use atomic routing signals and calibrate thresholds on held-out traffic.
- Measure false cheap routes and unnecessary escalations separately.
- Include retries, tools, validation, and cache effects in cost accounting.
- Keep long context on one model when cache economics dominate.
- Log routing decisions without leaking prompts or secrets.
- Canary the router on a small traffic segment.
- Keep an emergency bypass that sends all traffic to the proven baseline.
Frequently Asked Questions
What is cost per successful task?
It is the total cost of completing a set of tasks—including routing, model calls, thinking, tools, retries, and validation—divided by the number of tasks that actually pass your success criteria.
Should every Gemini agent use a model router?
No. Google itself recommends starting with a lighter model configuration first. If Gemini 3.8 Flash on low thinking already meets your quality and latency targets, a router may not justify its complexity.
Does lowering maxOutputTokens reduce thinking cost?
Not reliably. Google's November 3 experiment found that a tighter output ceiling did not reduce thinking on easy tasks and caused failures on some harder tasks. Configure thinking level directly when the model supports it.
Is Gemini 3.5 Flash-Lite always the best cheap path?
No. It is a current cost-efficient option for high-volume work, but your cheap path should be selected by your own task distribution, quality threshold, latency requirements, and current pricing.
Can a regex router be enough?
For a narrow, stable workload it can be. Evaluate it on held-out traffic. Prompt length and keywords often correlate poorly with the actual reasoning depth required.
Why can routing hurt context caching?
Model-specific caches are easiest to reuse when repeated turns stay on the same model. Switching between models can require multiple caches or reduce reuse, which can erase some routing savings on long-context agents.
Final Takeaway
The important shift in Google's November 3 guidance is conceptual: stop treating price per million tokens as the primary optimization target for an autonomous agent.
First find the cheapest single configuration that reliably completes your tasks. Then, if your traffic contains a meaningful mix of simple and difficult work, test a lightweight classifier that escalates only the tasks that need stronger reasoning.
Do not route by intuition. Do not assume an output cap reduces thinking. Do not ignore cache economics. And do not celebrate a lower API bill if the cheap path quietly creates more failed tasks.
The metric that matters is the one closest to the product outcome: cost per task done right.
Official Sources
- Google Developers Blog: Cost per task — using cheap classifiers to route across Gemini models and thinking levels
- Gemini Developer API pricing
- Gemini 3.5 Flash-Lite model documentation
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
