Cloudflare Web Search API: How to Ground AI Agents with Live Web Data
A practical guide to REST, Workers, providers, pricing, BYOK, citations, and production safeguards
Cloudflare launched Web Search API in open beta on October 2, 2026. It gives AI agents a single endpoint for searching the public web and returns structured results that can be passed into a model as current context. The launch matters because it separates web retrieval from model inference: an application can choose a search provider, inspect the source URLs, and keep search activity inside AI Gateway's logging, billing, and access-control layer.
This guide shows the REST and Workers paths, compares the three launch providers, calculates transparent request costs, and identifies the production checks that the launch documentation does—and does not—cover. All product facts and prices were checked against Cloudflare's official documentation on October 5, 2026. Recommendations are clearly labeled as Rubic8 analysis rather than measured benchmarks.
What Cloudflare Web Search API actually does
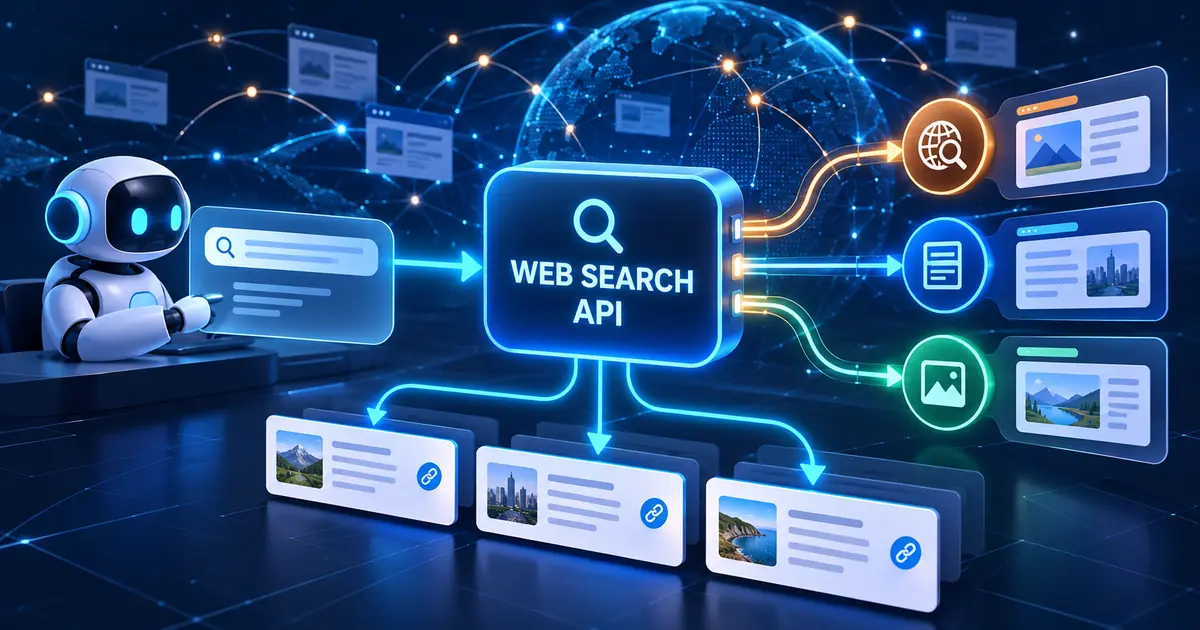
An AI model does not automatically know what happened after its training cutoff, and it should not invent a URL when it needs current information. Web Search API accepts a query and returns a normalized list of results. Each result includes a URL, title, and description; optional fields can appear when a provider supplies them. The response also contains request metadata such as the original query, a request ID, and latency in milliseconds.
The API runs through Cloudflare AI Gateway. Cloudflare says search calls receive the same logging, analytics, billing, and access controls used for model inference. At launch, the provider parameter supports Ceramic.ai, Exa, and Linkup. All three map into the same core response shape, so changing the provider does not require rewriting the consumer that reads items.
This is different from asking a chat model provider to run its own native search tool. Cloudflare also documents native web-search tools for several model providers through AI Gateway, but the new standalone Web Search API is a separate provider-neutral retrieval call with its own endpoint and search-provider choice. It is also different from Cloudflare AI Search, which is designed to retrieve from data that you index for your own application. Use Web Search API when the target corpus is the live public web.
Quick answer: when should you use it?
Use Web Search API when an application needs recent public information, source URLs, or a consistent retrieval interface across search providers. Examples include a documentation assistant checking a newly released API, a support agent finding the current policy page, or a research workflow collecting sources before it asks a model to summarize them.
Do not treat search results as verified truth. A result is evidence to inspect, not permission to repeat every snippet. Pages can be wrong, stale, manipulated, or irrelevant. Your application still needs source selection, date checks, prompt-injection defenses, and a policy for what the model may claim.
Prerequisites and authentication
According to Cloudflare's official how-to guide, you need a Cloudflare account, an AI Gateway, and either AI Gateway credits or a stored provider key. Every account has a gateway named default, although production teams will often use a named gateway to make ownership and logging clearer.
For the REST endpoint, create a Cloudflare API token with both of these account-level permissions:
- Workers AI > Read
- AI Gateway > Read
Keep the token on a server. Do not expose it in browser JavaScript, a mobile binary, a public repository, an analytics event, or a support screenshot.
REST API example
The REST endpoint is:
POST https://api.cloudflare.com/client/v4/accounts/{account_id}/ai/websearch/A minimal cURL request can look like this:
curl "https://api.cloudflare.com/client/v4/accounts/$CLOUDFLARE_ACCOUNT_ID/ai/websearch/" \
  --request POST \
  --header "Authorization: Bearer $CLOUDFLARE_API_TOKEN" \
  --header "Content-Type: application/json" \
  --data '{
    "query": "Cloudflare Web Search API open beta documentation",
    "provider": "ceramic",
    "limit": 5,
    "options": {
      "gateway": { "id": "default" }
    }
  }'
The required query can contain 1 to 1,024 characters. The provider value can be ceramic, exa, or linkup; Ceramic is the default when the field is omitted. The limit can be 1 through 10 and defaults to 10.
A normalized response follows this pattern:
{
  "items": [
    {
      "url": "https://example.com/current-docs",
      "title": "Current product documentation",
      "description": "A query-relevant description..."
    }
  ],
  "metadata": {
    "query": "Cloudflare Web Search API open beta documentation",
    "requestId": "<REQUEST_ID>",
    "latencyMs": 612
  }
}
Use Rubic8's JSON Formatter to make a saved response easier to inspect and the JSON Validator to catch syntax errors in test fixtures. Remove tokens, personal data, confidential queries, and internal URLs before pasting any payload into an online tool.
Cloudflare Workers example
Workers can call the same product through the AI binding. Add an AI binding named AI to the Wrangler configuration, then call env.AI.websearch():
export default {
  async fetch(request, env): Promise<Response> {
    const response = await env.AI.websearch({
      gatewayId: "default",
      query: "What changed in the latest Cloudflare Workers release?",
      provider: "exa",
      limit: 5,
    });

    if (!response.ok) {
      return new Response("Search unavailable", { status: 502 });
    }

    const results = await response.json();
    return Response.json(results);
  },
} satisfies ExportedHandler<Env>;
websearch() returns a standard Response. The explicit status check above is a Rubic8 production recommendation; the short official example proceeds directly to response.json(). Add timeouts, structured error logging, and a user-facing fallback that matches the importance of the task.
Provider comparison and current pricing
Cloudflare publishes the following list prices when requests are paid with AI Gateway credits. Cloudflare says it adds no markup. Prices and product terms can change, so verify the provider page before budgeting or deploying.
| Provider | Documented behavior | ZDR | Price per 1,000 requests |
|---|---|---|---|
| Ceramic.ai | Default; independent index of more than 40 billion pages; descriptions up to 8,000 characters | Yes | $0.25 |
| Exa | auto search type; page highlights returned as descriptions |
Yes | $7.00 |
| Linkup | fast search depth; raw search results rather than a generated answer |
Yes | $5.00 |
Documented fact: these are request prices, not token prices, and all three providers are marked Zero Data Retention in the current provider documentation. Rubic8 analysis: start with the provider whose result format and economics fit the job, then evaluate the other two on a fixed set of representative queries. The provider descriptions are useful starting hypotheses, not proof that one provider is more accurate or faster for your workload.
Transparent cost examples
At the published list prices, 10,000 searches would cost $2.50 with Ceramic, $70 with Exa, or $50 with Linkup. Those figures are simple arithmetic, not invoice predictions. They exclude model inference, Workers usage, retries, storage, logs, taxes, provider-plan differences, and any future price change.
Search cost = requests / 1,000 × provider price

10,000 Ceramic searches = 10 × $0.25 = $2.50
10,000 Exa searches    = 10 × $7.00 = $70.00
10,000 Linkup searches = 10 × $5.00 = $50.00
A cheap search that produces unusable evidence can cost more after retries and review. Conversely, a richer result can waste context and money when a short lookup would have been enough. Measure cost per accepted task, not only cost per API call.
How to choose a provider without inventing a benchmark
Create a small evaluation set from real user intent: fresh documentation, a news event, an obscure technical error, a location-sensitive lookup, and a query with an ambiguous entity. Freeze the queries and the result limit. For each response, record:
- whether a correct source appears in the top results;
- whether the description supports the claim you need;
- source authority, publication date, and geographic relevance;
- end-to-end latency observed by your application;
- search calls, model calls, retries, and accepted-answer rate;
- the exact provider, date, gateway configuration, and prompt revision.
This produces evidence about your own workload. It does not justify a universal “best provider” claim. A provider may lead on one query class and trail on another. Re-run the set after material provider or application changes.
Bring your own provider key
Cloudflare supports BYOK for Ceramic, Exa, and Linkup. Store the provider key in AI Gateway, assign an alias, and pass that alias as byokAlias. Cloudflare says the request contains the alias rather than the secret, and stored keys are encrypted with Secrets Store.
{
  "query": "What is Cloudflare Workers?",
  "provider": "exa",
  "byokAlias": "production-search",
  "options": {
    "gateway": { "id": "default" }
  }
}
If an explicit alias is missing or incorrectly configured, the request fails with a 400 response rather than silently falling back to AI Gateway credits. If you omit byokAlias, AI Gateway first looks for a stored default alias for that provider; otherwise it uses credits. That behavior deserves a deployment test because it affects which organization receives the bill.
Using search as an agent tool
The safe pattern is a two-stage loop: let the model decide that current evidence is needed, execute the search outside the model, then provide the returned items as tool data. Require the final answer to cite the source URLs it actually used.
- Receive the user's question and determine whether freshness is material.
- Have the model emit a bounded
web_searchtool call. - Validate the query, provider, and result limit on the server.
- Run
env.AI.websearch()and reject failed or malformed responses. - Filter or rank sources according to your product policy.
- Pass selected results to the model with instructions to attribute factual claims.
- Return the answer with clickable source links and an “as of” date when freshness matters.
Do not allow tool output to override application policy. Search snippets and pages are untrusted input. They can contain instructions aimed at the model, hidden text, misleading claims, or content copied from another source. Separate data from instructions and constrain what downstream tools the model may call.
Production safeguards worth adding
1. Validate and minimize queries
Enforce Cloudflare's 1,024-character limit before the request. Remove credentials and unnecessary personal data. A support assistant rarely needs a customer's full message, email address, and account number in a public-web query; extract the technical issue instead.
2. Preserve source provenance
Store the query, provider, returned URL, title, request ID, and retrieval time alongside the generated answer when your retention policy permits it. Do not display a citation merely because it appeared in results: the cited page should support the nearby claim.
3. Design a fallback
Decide what happens when search times out, returns no suitable source, or the model cannot reconcile conflicting pages. A high-stakes application should decline or escalate rather than convert missing evidence into confident prose. Provider fallback may improve resilience, but automatic retries can multiply cost and latency.
4. Treat logs as data
AI Gateway observability is useful for debugging and cost analysis, but search queries can reveal product plans, customer problems, or security research. Configure access and retention intentionally. ZDR at the search-provider layer does not remove your responsibility for logs and systems you control.
5. Monitor quality, not just uptime
A 200 response can still contain irrelevant or weak sources. Track citation validity, source diversity, accepted-answer rate, corrections, and user escalation. Review failed examples instead of optimizing only an average latency chart.
Responsible crawling and publisher controls
Cloudflare says each launch partner has committed to its verified-bot requirements, to respecting robots.txt, and to returning a link to the source of each result. That is a meaningful design choice because it gives publishers visibility and gives applications material for attribution.
It is not a guarantee that every retrieved page is accurate, licensed for every downstream use, or suitable for model training. Retrieval, quotation, summarization, storage, and training are different uses. Product teams should apply their own legal, editorial, and privacy requirements.
Practical example: a release-note assistant
Imagine a developer asks, “Did this SDK change authentication this week?” The assistant searches for the official SDK documentation and release notes, ranks first-party sources above commentary, checks dates, and passes only the relevant descriptions and URLs to the model. The answer states what the sources document, links to them, and says when the search ran.
This example is a proposed workflow, not a benchmark of Cloudflare or any provider. Its value comes from explicit acceptance rules: at least one first-party source, a date within the requested period, no claim unsupported by a retrieved page, and a safe “not enough evidence” outcome.
Frequently asked questions
Is Cloudflare Web Search API generally available?
No. Cloudflare's official overview labels it open beta as of October 5, 2026. Beta interfaces, limits, pricing, and behavior can change.
Does the API generate the final answer?
The standalone endpoint returns structured search results. Your application decides whether and how to send those results to a model. Linkup is specifically documented as returning raw search results rather than generating an answer in this integration.
Can I switch providers without changing my parser?
The core response is normalized to the same item shape, which reduces integration work. Optional fields and description content can still differ, so keep the parser defensive and test all providers you enable.
Is Zero Data Retention enough for sensitive queries?
No single label replaces a data-flow review. Check the current provider terms, AI Gateway logging, your own logs, model calls, and any storage or analytics system that receives the query or results.
Which Rubic8 tools help with implementation?
Use the JSON Formatter and JSON Validator for sanitized fixtures, and the JavaScript Beautifier when reviewing a compressed Worker example. These tools check presentation or syntax; they do not validate source quality, permissions, or business logic.
What Rubic8 would build next
A useful companion would be a Web Search API cost calculator that compares provider request prices, monthly volume, retry rates, and model costs with a visible pricing date. That tool does not exist on Rubic8 today, so this article does not link to or imply an available implementation.
Final take
Cloudflare Web Search API gives developers a compact retrieval layer for live public-web context: one REST endpoint or Workers binding, three launch providers, normalized source-linked results, unified billing, and gateway observability. The integration is straightforward; the harder work is deciding what counts as sufficient evidence.
Start with a narrow use case and a fixed evaluation set. Preserve citations, validate inputs, budget retries, and let the system say it lacks evidence. That produces a more trustworthy agent than simply adding search and assuming freshness equals correctness.
Official sources
- Cloudflare Blog: Introducing Web Search API via AI Gateway — October 2, 2026
- Cloudflare Web Search API overview — last updated October 2, 2026
- How to use Web Search API — last updated October 2, 2026
- Web Search API providers and pricing — last updated October 2, 2026
Last reviewed: October 5, 2026. Verify beta limits, prices, provider terms, and security requirements against the official documentation before production use.
Rubic8 Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
