EmbeddingGemma 2: A Practical Guide to Private Multimodal Search and RAG
Build a local retrieval pipeline for text, code, and media, then measure quality before deployment.
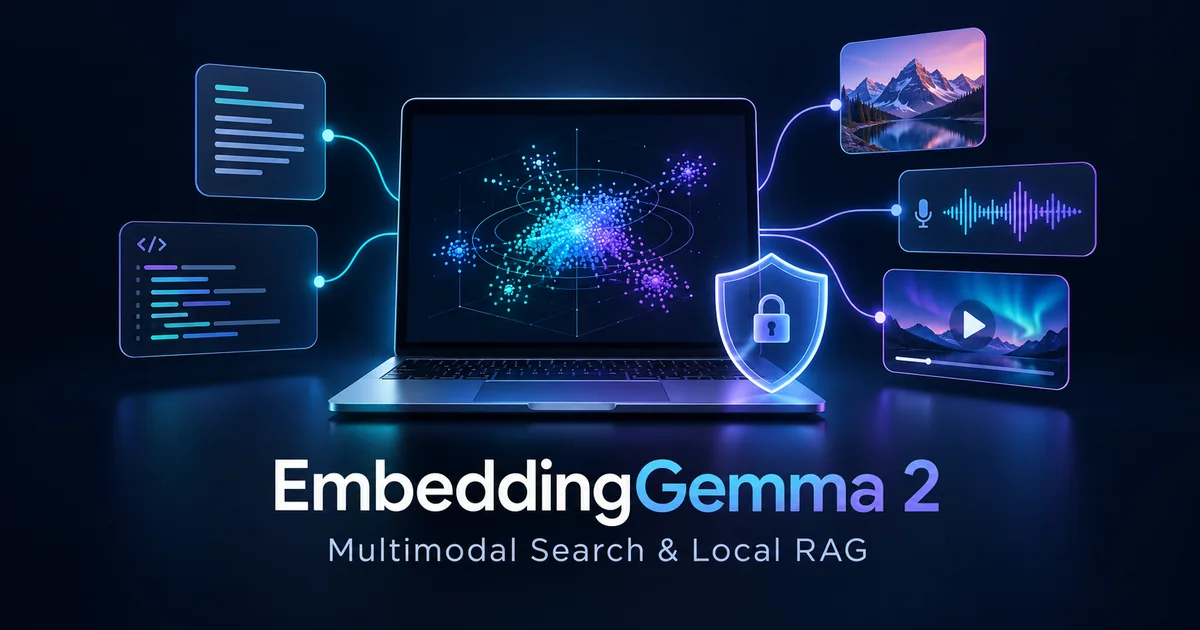
EmbeddingGemma 2 is an open multimodal embedding model for local semantic search and retrieval-augmented generation (RAG). It lets developers search private collections using meaning across text, code, and media. Google announced the model on October 6, 2026, according to its official launch post and Gemma release history. That makes it a timely candidate for experiments with local retrieval.
This guide turns that release into a practical project: a small searchable document collection, an optional image index, and a retrieval layer for RAG. The examples are illustrative implementations based on Google's documented interface; they have not been benchmarked by Rubic8. Treat the evaluation plan as part of the implementation, rather than assuming a model announcement guarantees good results on your files.
In this guide: Model overview · Python text search · Image retrieval · Vector storage · Local RAG · FAQ
What is EmbeddingGemma 2?
An embedding model converts an input into a numeric representation. A search application compares representations and returns nearby items. A generative model can then use those items to write an answer. Keeping these responsibilities separate makes failures easier to diagnose: poor search results call for retrieval work; an unsupported answer despite good evidence calls for generation or prompting work.
Google describes EmbeddingGemma 2 as a Gemma 4-based model with a shared 768-dimensional space for text, code, images, audio, and video. The full configuration is approximately 740 million parameters, with an 8,192-token context and an Apache 2.0 license. See the official model card for architecture, evaluation, and limitations.
A shared space enables a useful product experience: someone can describe a picture without knowing its filename, or search source code using a plain-language question. Still, similar meaning does not establish correctness, ownership, or permission to access a result. Those rules belong in your application.
EmbeddingGemma 2 model sizes and encoder selection
| Collection | Approximate active parameters | Configuration |
|---|---|---|
| Text and code | 270M | Disable vision and audio encoders |
| Text and images | 440M | Disable audio encoder |
| Text and audio | 570M | Disable vision encoder |
| All supported modalities | 740M | Default configuration |
These rounded sizes describe active model components, not a guaranteed memory budget. Your runtime also needs space for temporary tensors, input decoding, vector storage, and the rest of the application. Measure the entire process on the target machine, including a large input and a concurrent search.
Start with one concrete job
For a repository assistant, begin with text and code. For a design library, begin with text and images. Add a modality only when your users have a retrieval task that needs it. This keeps the first evaluation manageable and prevents media preprocessing from obscuring ordinary ranking problems.
Before indexing, write three example questions and the exact files that should answer each one. Include a question with no answer in the collection. These examples establish whether your application needs semantic matching, exact identifiers, or both. A search for an error code often needs keyword matching even when a natural-language question benefits from vectors.
Build local semantic search with EmbeddingGemma 2 in Python
Use a dedicated environment for the prototype. Google's Sentence Transformers inference guide documents loading the model, task prompts, and truncation. Install current compatible dependencies, then record the versions that actually work in your environment.
pip install -U sentence-transformers transformersPrecision: Google documents support for bfloat16 or float32 and warns that float16 is incompatible with this model. Confirm the loaded dtype when adapting the example to a GPU.
The following example loads the text components and retrieves short passages. It uses a CPU for a straightforward prototype, rather than implying that every laptop will meet your latency target. The first run downloads model assets; offline operation requires preparing those assets locally beforehand.
from sentence_transformers import SentenceTransformer

model = SentenceTransformer(
    "google/embeddinggemma-2",
    device="cpu",
    config_kwargs={"vision_config": None, "audio_config": None},
)

passages = [
    "The deployment service retries failed uploads with exponential backoff.",
    "The image worker produces WebP thumbnails from uploaded photographs.",
    "The account service removes expired sessions every night.",
]
vectors = model.encode(
    passages, prompt_name="Document", normalize_embeddings=True
)
query = model.encode(
    ["How are failed uploads retried?"],
    prompt_name="SearchQuery", normalize_embeddings=True,
)
scores = model.similarity(query, vectors)[0]
for index in scores.argsort(descending=True)[:3].tolist():
    print(float(scores[index]), passages[index])
Keep query and document formatting consistent
The model card distinguishes retrieval queries from indexed documents. Use the documented task prompt for the query and the document format for corpus items. For code search, it lists CodeRetrieval as the query prompt. Do not combine an automatically applied prefix with the same prefix manually.
Store the formatting decision with the index configuration. If you later change document formatting, rebuild the affected vectors and rerun the evaluation. Otherwise, a ranking difference may come from inconsistent preprocessing rather than a meaningful model improvement.
For a coding assistant that needs current public Google documentation alongside repository context, see Rubic8's Google Developer Knowledge API and MCP guide. Keep that remote documentation route separate from the local code index, and make source provenance visible in the answer.
Preserve identifiers alongside vectors
The three strings above are only a demonstration. A real index needs stable records containing an identifier, source location, content hash, title, and access policy. Keep the original text available for displaying results. Embeddings are useful for ranking, but they cannot reconstruct the passage or prove where it came from.
For a public sample metadata file, Rubic8's JSON Formatter can make records easier to inspect. Use synthetic examples or public data when working in a browser tool; keep private corpus inspection inside your local workflow.
Chunk documents around useful evidence
A large context window does not make a whole document the best retrieval unit. A long handbook may cover several unrelated tasks. One vector for the entire handbook can make a specific procedure difficult to retrieve and can give the answer model far more material than it needs.
Start by splitting on meaningful boundaries such as headings, functions, or complete paragraphs. Keep enough surrounding text to explain a result. For source code, retain the filename and symbol name. For a procedure, keep prerequisites with the steps they qualify. Avoid cutting a warning away from the instruction it changes.
Use small overlaps only where they preserve continuity. Excessive overlap fills the top results with nearly identical chunks. Track a parent document identifier so you can group duplicates and retrieve neighboring context when needed. Your objective is a compact set of distinct, usable evidence, not the greatest possible number of chunks.
Add multimodal image search
Google's multimodal guide accepts images through dictionaries containing an image field. Its examples compare image embeddings with text in the same space. Load the vision component for this workflow.
# Additional dependencies for image inputs:
# pip install -U pillow

vision_model = SentenceTransformer(
    "google/embeddinggemma-2",
    device="cpu",
    config_kwargs={"audio_config": None},
)
images = [{"image": "assets/workshop.jpg"},
          {"image": "assets/forest-trail.jpg"}]
image_vectors = vision_model.encode(images, normalize_embeddings=True)
text_vector = vision_model.encode(
    ["A path through a forest"],
    prompt_name="SearchQuery", normalize_embeddings=True,
)
print(vision_model.similarity(text_vector, image_vectors))
Replace the example paths with files you own and can process. Decide whether orientation, cropping, captions, and duplicate images affect the task. A screenshot search and a photography library need different evaluation questions. Test both specific descriptions and broader concepts, and examine the returned image rather than judging only its score.
For audio and video, index retrievable segments with timestamps. Returning a two-hour recording without the relevant interval creates work for the user. Keep segment boundaries, original media locations, and decoding settings in metadata so results can be replayed and reindexed consistently.
Reduce embedding dimensions and vector storage
EmbeddingGemma 2 supports 768, 512, 256, and 128 dimensions through Matryoshka Representation Learning. Google's inference documentation shows using truncate_dim with normalization. Keep query and corpus dimensions identical.
compact_vectors = model.encode(
    passages,
    prompt_name="Document",
    truncate_dim=256,
    normalize_embeddings=True,
)
compact_query = model.encode(
    ["How are failed uploads retried?"],
    prompt_name="SearchQuery",
    truncate_dim=256,
    normalize_embeddings=True,
)
print(model.similarity(compact_query, compact_vectors))
For one million float32 vectors, raw numeric storage is approximately 3.072 GB at 768 dimensions, 1.024 GB at 256, and 0.512 GB at 128, using decimal units. This arithmetic excludes identifiers, text, database overhead, and search indexes. Measure the final database before claiming a product-level storage saving.
Compare compact vectors against your full-dimensional baseline using the same queries. If the small representation loses the one passage a user needs, its storage saving may be a poor trade. Conversely, a compact index that preserves useful results can make offline deployment easier.
Build a grounded local RAG pipeline
A basic RAG pipeline has five stages: prepare documents, embed chunks, retrieve candidates, select evidence, and generate an answer. EmbeddingGemma 2 handles the embedding stage. You still choose the search index, permission checks, answer model, and user interface.
Pass selected passages to the answer model with their source identifiers. Ask for citations attached to claims and an explicit acknowledgement when the evidence is insufficient. Include the actual passages, not just their similarity scores. A high score indicates a close representation; it does not turn a passage into authoritative evidence.
Protect the boundary between evidence and instructions
Retrieved documents may contain commands, advertisements, or malicious instructions. Treat them as evidence to read, not instructions that can change the assistant's rules. Keep system instructions separate from retrieved content and validate any tool action independently. A local index can still contain an untrusted file.
Apply access controls during retrieval and recheck them before showing excerpts. If a document is deleted or access is revoked, remove or invalidate its chunks. Updating the source file without updating the vector index can leave stale information available to search.
Evaluate retrieval before choosing a deployment target
Create a small, versioned test set from actual tasks. Label relevant sources for each query. Include paraphrases, filenames, exact identifiers, ambiguous requests, and questions that cannot be answered. Keep a separate set for iteration so you do not tune exclusively to the final evaluation.
- Recall at k: Does the useful source appear among the first k results?
- Ranking quality: Is the best evidence near the top, rather than buried under duplicates?
- Latency: Measure both initial startup and repeated queries.
- Resource use: Record peak memory, disk size, and indexing time.
- Answer grounding: Check whether generated claims follow the retrieved evidence.
Inspect failed queries individually. Try changing one variable at a time: chunk boundaries, formatting, dimensions, keyword retrieval, or candidate count. This produces an explanation for a quality change and a reproducible configuration you can deploy.
When a question needs recent public information outside your indexed collection, add a separate web retrieval route. Rubic8's Cloudflare Web Search API guide covers that workflow. Label results by source type and keep private passages out of public-web queries.
Local embeddings vs managed embedding services
Local embeddings are attractive when the collection must remain on a device, connectivity is unreliable, or repeated queries make predictable local processing useful. They also create operational work: model distribution, storage management, dependency updates, and testing across hardware.
A managed embedding service may be easier when a central backend already holds the documents and you need uniform infrastructure. Compare the whole system rather than only per-request pricing. Include indexing refreshes, staff time, hardware constraints, and the quality of results for your actual collection.
Local embeddings alone do not make an entire RAG application private. A cloud answer model, remote image URL, analytics event, or crash report can still transmit data. Review the complete path from ingestion to answer display and define what “offline” means for your product.
EmbeddingGemma 2 FAQ and deployment checklist
Does this replace a generative model?
No. Use it to create representations for retrieval and related tasks. Add a separate answer model if your product needs written responses. For many file-search applications, showing accurate ranked results is already a useful first release.
Can existing vectors be reused?
Do not assume vectors from another model are compatible. Plan a new index and migration test. Store the model identifier, revision, dimensions, and preprocessing settings with each index so future updates can be compared safely.
What should be ready before rollout?
Have a tested index configuration, a repeatable rebuild process, permission handling, source citations, and an evaluation report. Test the no-result case and the deleted-document case. Roll out to a small collection first, inspect failures, and expand only when search quality and resource use meet the product's requirements.
Editorial verification: Release date and model-specific details were checked against Google's official sources on October 9, 2026. Code samples are illustrative and require validation in your chosen environment. No Rubic8 performance benchmark is claimed.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
