GitHub Agentic Workflows GA: Setup, Security and Cost Controls
A practical rollout plan for repository automation with reviewable outputs and measurable costs.
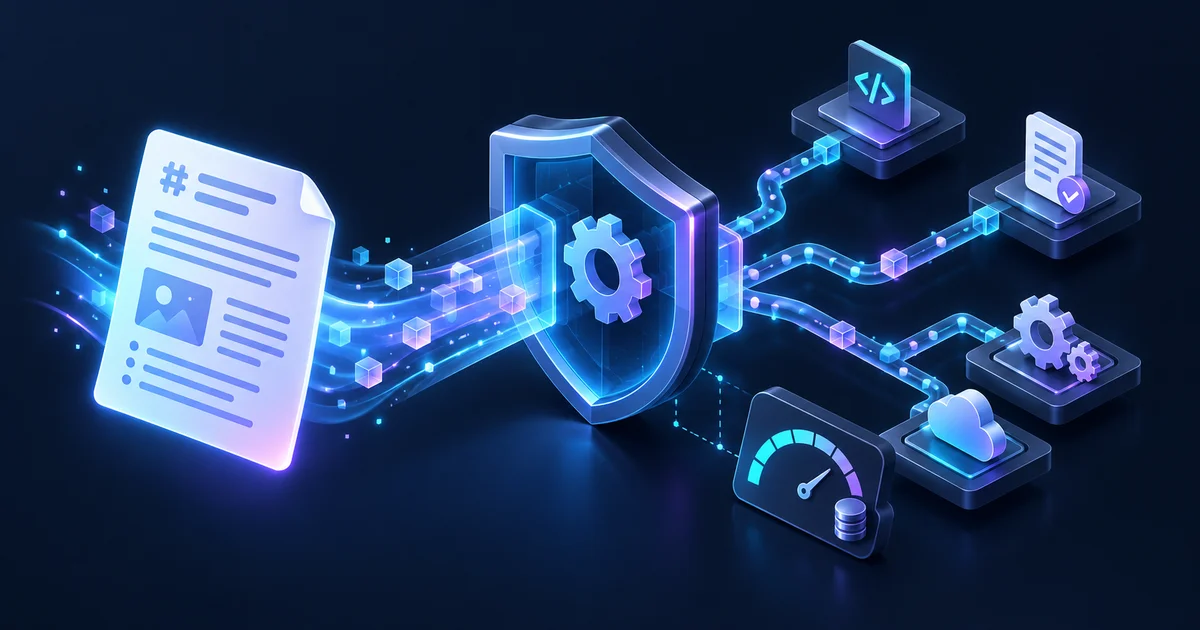
Updated October 30, 2026. GitHub Agentic Workflows became generally available on October 28, 2026. It brings coding agents into GitHub Actions for tasks such as issue triage, CI investigation and documentation maintenance. This guide explains how to evaluate it with a small, reviewable pilot before increasing its scope.
What GitHub Agentic Workflows changes
You describe an automation in Markdown, and the tool compiles it into an Actions YAML workflow. The resulting automation uses your existing runner groups and policy constraints. GitHub says the default Copilot CLI engine requires a Copilot license; general availability covers GitHub Free, Team and Enterprise on github.com. See the October 28 GA announcement.
The practical distinction is between specifying a fixed sequence and asking an agent to reason over evidence. A formatter has a predictable transformation. Investigating an unfamiliar CI failure may require reading logs, comparing changes and explaining uncertainty. Our recommendation is to reserve agent runs for the second kind of work.
Choose a pilot with an observable outcome
Start with one repository and one question that a maintainer can verify. For example: “Which open issues need a reproduction?” Define success before installation: the report cites the relevant issue, identifies missing information and avoids proposing changes unsupported by the evidence.
| Candidate | Useful first output | Review question |
|---|---|---|
| Issue backlog | A proposed triage report | Are labels and missing details justified? |
| CI investigation | A failure explanation with links | Does the evidence support the diagnosis? |
| Documentation | A proposed correction | Does it match the current code? |
These are suggested evaluation patterns, not measured performance claims. Keep the first pilot away from production deployment, billing changes and broad repository administration. Give a named maintainer responsibility for deciding whether each output is useful.
Install the extension and inspect a sample
The official quickstart requires a repository you can write to, Actions enabled, an authenticated GitHub CLI and a supported AI account. It supports Linux, macOS and Windows through WSL. From the repository directory, the documented starting commands are:
gh extension install github/gh-aw
gh aw add-wizard githubnext/agentics/repo-status
The wizard selects an engine, configures authentication and adds the Markdown source plus its generated lock file. It may offer to push changes or run immediately. Read those choices before accepting them. The sample gathers repository activity and creates a status issue, so an initial run has an observable side effect.
For a controlled pilot, review the proposed files before starting a run. Confirm the repository, trigger and destination for outputs. Follow the selected engine's current authentication instructions; keep credentials in the supported secret or token mechanism, never in the workflow prompt.
Keep the source and generated workflow together
After changing workflow frontmatter, the quickstart instructs you to compile again and commit both the Markdown file and generated .lock.yml. A typical review sequence is:
gh aw compile
gh aw status
gh aw run repo-status
Run the final command only when you intend to start that workflow. Review the generated diff as well as the natural-language instructions. A useful review asks what data enters the agent, what the agent can request and which job applies the result. A friendly prompt is not a permission boundary.
Use staged outputs before applying changes
GitHub documents staged mode for previewing proposed outputs. Add staged: true inside safe-outputs. The following is a configuration fragment to merge into a complete workflow, not a standalone runnable file:
safe-outputs:
  staged: true
  create-issue:
    title-prefix: "[pilot] "
Inspect previews in the Actions run summary, revise the instructions and repeat. Staged mode previews outputs; it does not mean the agent performs no computation or incurs no cost. Per-output staged settings can differ, so check the complete configuration rather than assuming every operation is preview-only.
The safe outputs reference explains the separate write job: an agent can request an issue, while a job with the necessary permission creates it. Explicitly enumerate the outputs your pilot needs. The reference also describes automatic issue-reporting defaults when no non-system safe outputs are configured, so omission should not be treated as proof that no issue can be created.
Review the security boundary
The security architecture describes layered controls including validation, isolation, integrity filtering, restricted network access and threat detection. Agents are read-only by default, while permitted writes go through output handling. Those protections are useful, but they do not establish that a diagnosis or patch is correct.
Our suggested review checklist is concrete: identify who can trigger the workflow; identify untrusted issue text or pull request content; list available tools and outbound destinations; check which secrets are accessible to which jobs; and inspect the permissions of output jobs. Treat instructions found in repository content as data to evaluate.
The quickstart specifically warns about pull_request_target, which uses the base repository's privileged context. Prefer pull_request where appropriate. If the privileged trigger is necessary, follow the official checkout guidance and avoid executing an untrusted pull request head in that context.
Budget for inference and Actions separately
The cost management reference separates runner usage from inference. AI Credits are a monitoring estimate: 1 AIC represents US$0.01, but the documentation says estimates may differ from actual provider billing. Verify charges in the provider dashboard. Threat detection also has its own budget.
Current documentation lists default limits of 1,000 AIC per run and 5,000 per workflow over 24 hours. These defaults are guardrails, not a quote for your workload. Choose smaller pilot limits appropriate to your team and check the installed version's configuration support. For example, these top-level frontmatter values express an intentionally limited experiment:
max-ai-credits: 100
max-daily-ai-credits: 500
Those values are examples, not a recommendation that every task can finish within them. Track failed and capped runs too: a cheap run that produces unusable output has not demonstrated value. Review the billing documentation for the selected engine and account arrangement before scaling.
Inspect logs without publishing private data
Use gh aw logs to inspect aggregate run metrics and gh aw audit <run-id> for a particular execution. When reviewing a JSON metrics export, Rubic8's JSON Formatter and JSON Validator can help inspect structure. Remove tokens, private repository details and sensitive log content before pasting data into any web tool.
A valid JSON document does not prove the agent's conclusion is correct. Keep evidence review separate from format checking: open the cited issue, compare the relevant code and reproduce the failure when practical. Record both the run cost and the review effort.
Decide whether to expand the pilot
Use a small scorecard across several representative runs. Record whether the output was accurate, actionable, duplicative or misleading. Include quiet days and ambiguous issues, not only a hand-picked successful example. Write down why a maintainer accepted or rejected each result.
| Signal | Record | Decision |
|---|---|---|
| Evidence quality | Correct references and explicit uncertainty | Revise prompts if claims cannot be checked |
| Operational cost | Inference, runner use and review effort | Adjust frequency or scope |
| Output noise | Repeated or unnecessary reports | Reduce automatic writes |
| Failure handling | Who notices and responds | Assign ownership before expansion |
Our recommended next step is narrow: expand either the number of repositories or the permitted output types, then evaluate again. Changing both at once makes it harder to understand why quality or spending changed. Keep a simple procedure for stopping the workflow and a maintainer who can use it.
Frequently asked questions
Does GA mean every runtime is generally available?
No. The project overview still labels Cloud Hypervisor and NVX runtimes as preview and notes that host eligibility varies. Check the exact runtime rather than extending the overall GA label to every option.
Should every CI task use an agent?
Use deterministic checks for rules that are already precise. Add reasoning where investigation or synthesis is needed, and measure whether its output improves a maintainer's decision.
Was this workflow tested in a Rubic8 production repository?
No. This article is a documentation-based setup and evaluation guide. Commands and fragments were checked against official documentation on October 30, 2026; no production execution, performance benchmark or guaranteed saving is claimed.
Rubic8 Editorial Team
Editorial Team
Rubic8 creates practical guides and free tools for developers, webmasters, and digital publishers. Our fast-changing technical content is reviewed against current primary documentation before publication.
